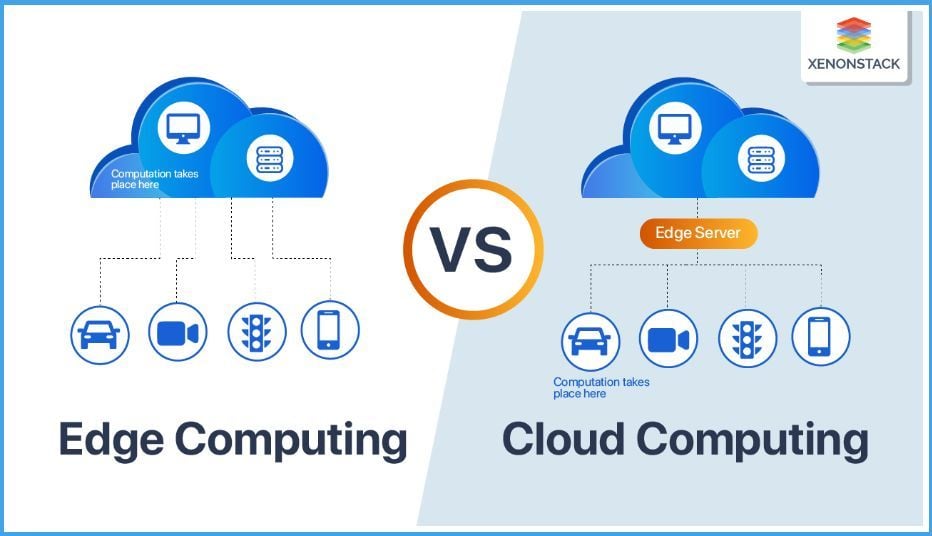
Edge computing vs cloud computing comes down to where the computation runs. Neither technology wins outright. NIST defines cloud computing as on-demand network access to a shared pool of configurable resources that can be rapidly provisioned and released with minimal management effort. Edge computing puts substantial compute and storage close to the devices, sensors and machines that produce data, and Shi et al. (2016) define the edge as any computing or network resource on the path between data sources and cloud data centres. A workload belongs at the edge when latency, bandwidth, privacy or offline operation make the round trip to a distant data centre too slow, too costly or too fragile. Otherwise the cloud’s larger compute wins, especially for the largest models or for work that can wait.
How Is Edge Computing Different from Cloud Computing, and Where Does Fog Fit?
The cloud is centralised. The LF Edge glossary describes it as on-demand access to shared computing resources that typically runs in a small number of large centralised and regional data centres. Edge computing is a form of distributed computing. ISO, as quoted in IETF RFC 9556, defines it as distributed computing in which significant processing and data storage take place on nodes at the edge of the network. The edge does both jobs: it handles upstream data from devices and downstream data from cloud services.
RFC 9556 adds a distinction that matters more than it first appears. What separates edge computing from a classic local system is that the edge uses management and orchestration features borrowed from cloud computing. Edge is not just “a server near the machine”. It is a server near the machine, run the way you would run cloud infrastructure.
Some of the neighbouring terms have formal definitions:
- Fog computing: Bonomi et al. (2012), who introduced the term at Cisco, describe it as a highly virtualised platform providing compute, storage and networking between end devices and cloud data centres, typically but not exclusively at the network edge. NIST SP 500-325 (2018) frames fog as decentralising applications, management and analytics into the network itself, because cloud-based IoT systems struggle with scale, heterogeneity and latency.
- Mist computing: the NIST fog draft (SP 800-191) describes mist as a lightweight layer of microcontrollers and microcomputers inside the network fabric, closest to the end devices, feeding fog nodes and possibly the cloud beyond them.
- Cloudlet: Satyanarayanan et al. (2009) define a cloudlet as a trusted, resource-rich computer or cluster that is well connected to the Internet and available to nearby mobile devices.
- Multi-access edge computing (MEC): ETSI defines it as an IT service environment with cloud-computing capabilities at the edge of an access network, close to its users.
Edge vs Fog Computing: The Sources Do Not Agree
People who search “edge computing vs fog computing” and expect one canonical answer will not find it in the sources. Shi et al. (2016) treat the two as interchangeable, with edge leaning towards the things side and fog towards the infrastructure side. The OpenFog Reference Architecture (2017) disagrees sharply: there, fog works with the cloud while edge is defined by the exclusion of cloud, and fog is hierarchical where edge tends to have few layers. RFC 9556 takes a middle line, using “fog” for multi-tiered edge computing with several layers between end devices and cloud services. The NIST draft defines the edge narrowly, as the layer made up of the smart end devices and their users.
The RFC 9556 framing is the most useful for engineering, because it describes topology rather than naming lineage. The term may be settling the question by default anyway: the LF Edge glossary records that “fog computing” has fallen into disuse in favour of more precise terms.
The Edge-Cloud Continuum in One Table
The LF Edge taxonomy attaches each tier to where it sits and what latency it supports.
| Tier | Where it sits | Latency the source attributes | Typical work |
|---|---|---|---|
| User (device) edge | User side of the last-mile network: devices, gateways, on-site servers | Lowest; avoids crossing the last mile | Hard real-time control such as brakes and airbags; local filtering |
| Access edge | Within 15 km of radio heads or cable headends | Sub-1 ms to 30 ms | Ultra-low-latency workloads needing a predictable last-mile connection |
| Regional edge | Metropolitan data centres on the service provider side | 30 ms to 100 ms | Workloads tolerant of tens of milliseconds |
| Central cloud | A few large centralised data centres | Internet path, varies by user location | Large-scale analytics, advanced machine learning, long-term historical storage |
If you want a gentler introduction to the device and gateway end of this table, our explainer on IoT edge computing and its benefits starts there.
Edge Computing vs Cloud Computing Pros and Cons, Measured
RFC 9556 names six requirements of many IoT applications that centralised cloud systems cannot satisfy: time sensitivity, data volume, connectivity cost, intermittent services, privacy and security.
Latency: Edge Usually Wins, but Not Everywhere and Not End to End
One large-scale measurement study compared edge and cloud latency directly. They measured latency from 8,456 end users to 6,341 Akamai edge servers and 69 cloud locations, and found that 58% of users reached a nearby edge server in under 10 ms, while only 29% got similar latency from the nearest cloud location. The same study found that more than 95% of users were better served by edge servers, although the cloud matched edge latency in some regions such as West Europe.
Two caveats keep that result honest. First, where cloud providers place their own “cloud edge” data centres in metropolitan areas, the residents of those cities get the fastest access, which Martin and Dogar (2023) describe as a digital divide between users near a data centre and users far from one. Second, edge shortens only the network leg of a call. Telnyx’s edge inference explainer points out that queueing, model compute and time to first token stay the same wherever the model runs, and a small edge model that escalates hard requests to a cloud model can be slower end to end than one call to a capable model in-region. Shi et al. (2016) make the same point from the other direction: the nearest physical layer is not always the best one, because a busy node adds waiting time.
How much latency matters depends on the loop the workload sits in. LF Edge separates latency-critical applications, which fail or behave destructively past a threshold, from latency-sensitive ones that merely degrade. A vehicle airbag is the first kind. Image processing is the second.
Bandwidth and Connectivity Cost
Raw sensor data is often too big to ship. RFC 9556 notes that industrial machines such as laser cutters produce more than a terabyte of data per hour, and that continuous high-bandwidth connectivity is unjustifiable for most IoT applications even though 5G or Wi-Fi 6 could in theory carry large uplink volumes. For video, Ananthanarayanan et al. (IEEE Computer, 2017) give 5 Mbps for HD and up to 25 Mbps for 4K per stream, and report that uplinks from private clusters to the cloud are usually too small for many high-resolution feeds. OpenFog calls the cost of moving data up the stack a “network tax”.
Privacy and Sovereignty
Computing on sensitive data close to where it is generated helps maintain privacy. RFC 9556 gives the example of smart-meter data that can reveal employment, family status, age and income, and notes that data stored indefinitely in the cloud raises leakage risk. It also describes edge nodes that anonymise or aggregate sensitive data before anything reaches a remote cloud. Keeping data inside a jurisdiction is a related constraint: Telnyx’s explainer notes that a central region may route data across borders, which matters to healthcare, banking and insurance customers under regional rules.
Offline Resilience
A cloud-dependent control loop loses control when the link drops. RFC 9556 notes that reliable services are difficult and partly impossible to deliver from the cloud for vehicles, drones or oil rigs with intermittent connectivity. OpenFog requires a mobile fog node to perform all required in-vehicle operations autonomously when it cannot reach other nodes or the cloud.
What the Cloud Keeps
The costs of edge are real. Many IoT devices have very limited hardware and need other nodes to support them. Some models are too large to run at the edge at all: Ananthanarayanan et al. cite VGG16 at 30 GFLOPs as best run in the cloud, if latency permits. Distributed systems are also harder to model: RFC 9556 names scale, mobility and resource management as challenges for simulation tools. The cloud gives what the NIST fog draft and Bonomi et al. call global centralisation, and OpenFog notes that the further a tier sits from the true edge, the more operational insight it can produce.
The summary is that edge buys proximity by giving up compute, and the cloud buys compute by giving up proximity.
When Should AI Inference Run at the Edge on IoT Devices Instead of in the Cloud?
Inference is the part of an AI system that moves outward. Training usually stays central. RFC 9556 describes distributed machine learning in which training runs at IoT gateways or in the cloud and inference runs on the devices. AWS documents the same pattern for IoT Greengrass, running inference on edge devices with cloud-trained models and keeping the cloud for training and complex processing. The reason is simple. Inference runs on every request, and every request pays the cost of distance.
Kang et al.’s Neurosurgeon work measured this trade-off directly. Across eight DNN applications in vision, speech and language, they found that the cloud-only approach spent over 94% of its time transferring data and less than 6% computing. For some applications, running locally on the mobile device was up to 11 times faster than cloud-only execution. The cloud still won on fast Wi-Fi, because its computational advantage only becomes an end-to-end advantage when the network is not the bottleneck.
Kang et al. also found that splitting a model between device and cloud can beat both extremes. For AlexNet on a mobile GPU over Wi-Fi, splitting the network between the last pooling layer and the first fully connected layer cut latency by 2.0 times compared with cloud-only processing. Across their benchmarks, Neurosurgeon’s partitioning improved end-to-end latency by 3.1 times and reduced mobile energy use by 59.5%, both as geometric means. Where to split depends on the model. Vision networks sometimes have good split points in the middle, while speech and language networks benefit more from splitting at the start or the end. Network state and data-centre load can move the best split point even for the same model.
Based on that evidence, we would put inference on the device or gateway when at least one of these holds, and keep it in the cloud otherwise:
- the decision sits inside a control loop or a conversation, where both delay and its variance matter;
- the input (video, high-rate sensor data) is much larger than the decision it produces;
- the uplink is slow, such as LTE or 3G, which is where Neurosurgeon’s throughput gains were largest;
- the data is personal or regulated and should stay on site.
The model also has to fit the edge hardware, since some models are too large to run there. Our edge AI deployment guide covering accelerator choice and quantisation deals with fitting models onto Jetson-, Coral- and Hailo-class devices, and the practical steps of deploying a vision model to edge hardware are covered separately.
Moving a Model to the Edge Is Porting Work
A model that performs well in a cloud training environment is a different artefact from one that performs on a constrained edge target, and closing that gap is engineering work rather than a hand-off. Moving inference from the cloud to an edge device is that kind of engineering work, so we would scope it against a measurable trigger such as a performance ceiling or a deployment-target constraint. What changes in the embedded workflow (unsupported operators, fallback paths, memory budgets) is covered in our article on developing embedded software for edge-AI devices.
How Do Edge and Cloud Work Together in an Edge-to-Cloud Architecture?
In an edge-to-cloud architecture, edge and cloud are two halves of one system, and the design question is which half does what. OpenFog states that the split between fog and backend cloud is application specific, and that it can change dynamically with processor load, link bandwidth, faults, security threats or cost targets. A recent state-of-practice survey of the edge-cloud continuum describes one division: edge nodes handle filtering, aggregation and basic inference to reduce data volume, and the cloud handles large-scale analytics.
Microsoft’s runtime, one layer of the edge tech stack, reflects that shape. Microsoft describes Azure IoT Edge as a device-focused runtime for deploying, running and monitoring containerised Linux applications for faster insights and offline decision-making, managed and scaled from the cloud through Azure IoT Hub. Containers suit the edge because they share the host kernel, which lowers overhead and makes applications run consistently across varied hardware. On the telecoms side, the ETSI MEC orchestrator selects hosts for an application based on constraints such as latency, available resources and services.
In Telnyx’s account, hybrid designs work best as a routing rule. In the Telnyx explainer’s examples, a small local model makes the first decision, such as whether a frame shows a defect, and only the cases that need more reasoning go to a larger model. The cost of that design is the extra hop on escalated requests, so it makes sense when the local decision filters out most of the traffic. The same split for camera pipelines is covered in our piece on where the workload splits between computer vision and cloud computing.
What Do Real Edge and Cloud Deployments Look Like?
The sources give several worked cases, and the factory and pipeline examples share one pattern. The fast, local reaction happens near the equipment, and the deeper analysis happens centrally.
- Smart factory: RFC 9556 places simple time-sensitive work such as temperature and humidity control at the edge, and sends analysis that needs high precision, such as machine life-cycle management or accident-risk prediction, to a central data centre.
- Oil pipeline: in OpenFog’s example, a cloud-only control loop could take several hundred milliseconds to react to an abnormal reading and loses control if the link fails. Local fog nodes react in milliseconds and contact the cloud only occasionally.
- Video analytics: Ananthanarayanan et al. call large-scale video analytics the killer application for edge computing. Filtering at the edge let their surveillance system cover an area 5 to 200 times larger for a fixed bandwidth than streaming every camera to the cloud.
- Vehicles: Shi et al. cite an autonomous car producing a gigabyte of data per second that needs real-time processing. LF Edge classes functions such as braking and airbag deployment as hard real-time work that is always done at the user edge.
- Face recognition: a proof of concept cited by Shi et al. cut response time from 900 ms to 169 ms by moving computation from the cloud to the edge.
- Cloud-side work: in the continuum model, large-scale analytics, advanced machine learning and long-term storage sit in the cloud layer.
Environmental sensing is another case of the same split, set out in our article on AI and IoT for air pollution. For autonomous systems and industrial lines in more depth, see the deployment trade-offs for edge AI applications.
Is Edge Computing Just On-Premise Infrastructure with a New Name?
Location is part of what makes something edge, but not all of it. Running cloud-style management and orchestration on that local hardware is the rest. An on-site server can be an edge node, but RFC 9556 separates edge computing from classic local systems by its use of cloud-derived management and orchestration. LF Edge says the same thing more bluntly: edge applications that do not use centralised cloud resources, remote management and orchestration, or CI/CD more closely resemble traditional on-premises applications.
The original cloudlet paper sets out the operational difference. Satyanarayanan et al. contrast the cloudlet, which holds only soft state, is self-managed, sits at business premises under decentralised ownership and serves a few users over LAN latency, with the cloud, which holds hard state, is professionally administered around the clock and serves hundreds or thousands of users over Internet latency. Physically an edge fleet resembles the cloudlet; by RFC 9556’s definition it must be run like the cloud.
Cost is where “edge vs on-premise” turns into “owned vs rented”. The available figures here come from a vendor. Lenovo’s 2026 TCO analysis of generative AI infrastructure claims breakeven in under six months for high-utilisation on-premises servers against on-demand cloud pricing, and explicitly excludes storage, egress and support costs from the cloud side. That is a vendor’s claim about data-centre GPU servers, not an edge measurement. The question it raises still transfers: owned hardware pays off when it is kept busy, and rented capacity pays off when demand is bursty.
Will Edge Computing Replace Cloud Computing?
No. The sources that make the strongest case for edge also expect the cloud to stay. OpenFog states that the traditional backend cloud will remain an important part of computing systems as fog emerges, and both the NIST fog draft and Bonomi et al. describe many applications as needing both fog localisation and cloud globalisation.
The share of processing near the source has been forecast to grow. Shi et al. (2016) cited a projection that 45% of IoT data would be processed at or near the edge by 2019, and RFC 9556 cites an expectation that 90% of IoT data will be stored, processed and acted on close to the source. Treat these as projections, not measurements. The cloud providers are also moving outward themselves. The 2025 continuum survey counts 34 near-edge zones for AWS against 36 cloud regions, and 71 near-edge zones for Google Cloud against 41 regions. The likely outcome is a blurrier line rather than a replacement, with “the cloud” increasingly including metro edge sites.
A Placement Checklist for One Workload
Placement is decided per workload, not per company. These are the questions to answer before choosing a tier:
- What loop does the output feed? If a missed deadline causes critical malfunction, as in hard real-time control, LF Edge places the work at the user edge. If it only degrades the experience, the Service Provider Edge serves it.
- What is the latency budget, end to end? Count queueing and compute as well as network time, and include escalation hops in hybrid designs.
- How large is the input compared with the decision? High-rate video and sensor streams favour filtering locally and sending results.
- Must it work offline? If the link can drop, reliable service from the cloud is difficult and partly impossible.
- Can the data leave the site or the region? Privacy risks and regional data rules bear on placement as well as performance.
- Does the model fit the target hardware? If it does not, the options include a split model or the cloud.
- Who will run the fleet? Without cloud-style orchestration you are running scattered on-premise servers, not an edge platform.
When the answers to 1, 3 and 4 all point to the cloud, edge adds operational cost without a matching gain.
FAQ
What Is the Full Form of “edge” in Edge Computing?
“Edge” is not an acronym. It refers to the logical extremes of a network, close to the devices and users, where edge computing places its resources.
Does AI Depend on the Internet?
Inference does not have to. A model deployed to an edge device can run on locally generated data, and runtimes such as Azure IoT Edge are built for offline decision-making. Training usually stays at gateways or in the cloud.