The reported benefits of MLOps include more frequent deployment, fewer production errors and lower operational costs, and monitoring with automated retraining helps maintain model accuracy. The tools behind those benefits have their own costs. No single product covers the whole lifecycle. Managed platforms trade control for convenience, and open-source stacks trade convenience for integration and maintenance work. So the pros and cons of MLOps tools come down to one question: does what you install match what your models need at their current stage?
The benefits of MLOps that hold up under measurement
A mixed-method study of ML DevOps adoption, posted to arXiv in 2025, reports that deployment frequency rose by 40% on average after adoption, production error rates fell by 25% and operational costs dropped by 30%. The authors credit the lower error rates to continuous monitoring and automated retraining, and the lower costs to automating repetitive tasks and allocating resources better. Deployment frequency was counted as successful model deployments per month, and error rates were tracked through automated logging and incident reports.
Treat those figures as one survey’s reported averages, not a forecast for your own environment. The same study says tools such as TFX, Kubeflow and MLflow need a substantial initial investment, that teams have to be upskilled to bridge data science and DevOps, and that 42% of respondents struggled to integrate ML-specific tools into their existing DevOps workflows. It also lists high initial implementation costs, cultural resistance and the continuing need for monitoring and retraining as obstacles.
Other benefits show up in daily engineering work. Kreuzberger et al. (2022) describe CI/CD automation as giving developers fast feedback on whether build, test and deploy steps succeeded, which raises productivity. They define reproducibility as the ability to rerun an ML experiment and get exactly the same results. A 2024 multivocal review by Eken et al. adds that version control of code, data and configuration lets a team roll back to the last working version of an ML system, which improves recoverability and fault tolerance. Google’s Cloud Architecture Center describes “experimental-operational symmetry”: the pipeline used in experiments is the same one that runs in preproduction and production.
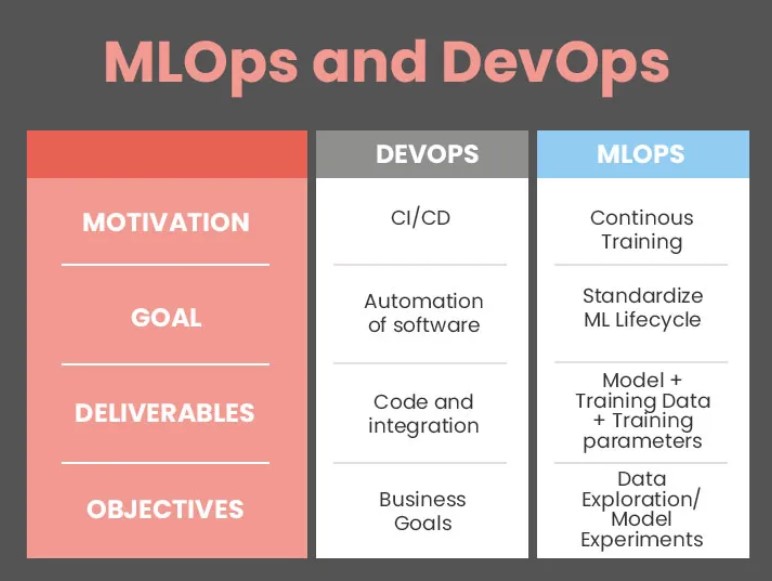
Models have properties that regular software does not. Models degrade silently when input distributions change, and their weights cannot be version-controlled the way a Python file can. The wider distinctions between MLOps and DevOps are covered on their own page.
What an MLOps tool stack has to cover
Kreuzberger et al. (2022) describe a reference architecture with these parts:
- a source code repository
- CI/CD automation
- workflow orchestration that runs pipelines as directed acyclic graphs
- a model registry that stores trained models with their metadata
- an ML metadata store that tracks parameters, metrics and lineage
- training infrastructure
- a monitoring component that feeds a loop back into retraining
Google’s guidance adds a feature store, so that training and serving read the same feature definitions.
A systematic review of MLOps tools posted to arXiv in 2026 found that no single product spans the entire lifecycle, so practitioners routinely build pipelines from several tools. Integrated platforms now bundle many of these capabilities. Our own roundup of platform consolidation describes the era of assembling 8 to 12 standalone tools giving way to integrated offerings from Databricks, AWS SageMaker, Google Vertex AI and others.
The glue code that wires tools together is costly in the long term. Sculley et al. (NeurIPS 2015) estimated that a mature ML system might be at most 5% machine learning code and at least 95% glue code. They warned that glue code tends to freeze a system to the quirks of a particular package, so testing alternatives becomes prohibitively expensive. Our tool-stack guidance describes the same pressure from the other side: teams new to MLOps often end up with six to eight tools where two or three would do, and the failure is rarely a missing capability but the cost of operating the tools they have.
Managed platform or open-source stack: which fits your team?
The systematic review describes a familiar compromise. Practitioners prefer community-maintained tools for experiment tracking and data versioning, but turn to commercial platforms when they need infrastructure that scales quickly and comes with operational support. Neither option is better in general. The comparison below shows what each one costs you.
| Factor | Managed platform (SageMaker, Vertex AI, Azure ML) | Open-source stack (MLflow, Kubeflow, DVC) |
|---|---|---|
| Infrastructure work | The provider handles provisioning and securing compute, storage and networking | Far more integration effort and long-term maintenance |
| Control | Practitioners lose fine-grained control, and the services may not meet specialised requirements | Greater control and customisation |
| Skills needed | SDKs such as SageMaker’s call for advanced programming skills | Kubeflow needs solid Kubernetes and containerisation experience |
| Support | Commercial operational support and fast scaling | Community-maintained |
| Lock-in | Companies accept the subscription fee and the risk of vendor lock-in | Glue code still ties a system to one package’s quirks |
| Typical fit | Teams that want to spend as little effort as possible on the platform itself | Larger teams and more mature projects |
Within open source, the tools differ in what they ask of you. MLflow is built for accessibility, with a simple web UI, thorough documentation and wide support for storage backends. Kubeflow is rooted in Kubernetes and offers modular components, fine-grained control and automatic scaling, but it takes a tougher setup and more operational know-how. The review’s authors conclude that comparing tools on features alone is not enough: the skills the team already has must count as well.
The two routes also mix. Amazon SageMaker is built with a modular architecture that accepts open-source tools and APIs, including PyTorch and Kubeflow. MLAIA, a practitioner blog, recommends using managed commodity infrastructure for compute and storage, open-source or open-standard tooling at the ML application layer, and treating any proprietary MLOps platform as a frontend for UI, dashboards and scheduling rather than as the backend contract for your data.
How hard is it to leave an MLOps platform once you depend on it?
Migrating off a platform takes a lot of time. Eken et al. note that migrating between MLOps platforms means extracting artifacts and the links between them, the workflows that create pipelines, and the underlying resource requirements, which takes a lot of time. MLAIA argues that teams consistently underestimate migration cost because they price the core platform replacement and ignore the CI/CD integrations, monitoring dashboards, data lineage tracking, team workflows and documentation built around it. The trigger is not always your choice either. A vendor shutdown forces a migration with a deadline, an acquisition causes gradual roadmap drift, and an acquired open-source project can fork so that your version stops getting security patches.
According to MLAIA, the lock-in risk is concentrated in application-layer tools such as experiment trackers, feature stores and model registries, where proprietary APIs and data formats hold the data. Commodity managed compute, object storage and managed Kubernetes carry much less of that risk.
A lock-in test to run before you commit
- Export every trained model with its parameters, metrics and lineage, then load it into a different tool. If that fails, your models are not reachable without the platform.
- Evaluate open-source alternatives for pipeline orchestration, such as Airflow or Prefect.
- Evaluate open-source alternatives for serving, such as Ray Serve or Triton Inference Server.
- Write the migration estimate to include CI/CD integrations, dashboards, lineage, team workflows and documentation, not just the platform swap.
- Decide what you would do if the vendor shut down, was acquired or forked its open-source edition.
Run this test during a trial, before you commit. Finding the answer during a forced migration costs far more.
Which MLOps capabilities does a first project need, and which are overengineering?
A first production model needs version control and data validation and monitoring from the start. Automated continuous training and a feature store earn their place when new data arrives constantly or training-serving skew becomes a risk, and Kubeflow orchestration demands Kubernetes skills. Both extremes cost money. Our infrastructure guidance notes that enterprise-grade MLOps infrastructure is often installed long before the first production model, which means months of platform work before any model delivers value, while having no discipline at all creates fragility that is expensive to unwind once a model becomes business-critical.
| Capability | For the first production model | When the fuller version earns its place |
|---|---|---|
| Version control of code, data and configuration | Needed from the start, because it allows rollback to the last working version | Always |
| Experiment tracking and metadata | A lightweight tracker such as MLflow is enough | As experiments multiply and model upgrades need a record of the decision behind them |
| CI/CD for models | When pipelines in production need rapid, reliable updates | |
| Data validation and monitoring | Needed early: data validation and monitoring should be treated as a key product feature from the start | Always |
| Continuous retraining | Manual retraining cued by monitoring | When a constant stream of new data makes retraining a repetitive task |
| Feature store | Not needed at first | When shared features risk training-serving skew |
| Kubernetes orchestration (Kubeflow) | Not needed at first | When the team has Kubernetes skills and can carry the tougher setup |
Microsoft’s Azure Architecture Center maturity model describes stages of maturity. At the most automated end, the full system is automated and easy to monitor, and drift or regression signals trigger retraining. The maturity model also states that as maturity rises, incidents and errors become more likely to feed into process improvements. These are levels to grow into, not the place to start. Sculley et al. make the general point: solutions that buy a tiny accuracy gain with a large increase in system complexity are rarely wise.
How small the stack can be while still producing a production-quality deployment is worked through in MLOps for organisations that have never operationalised a model. The sequencing of the underlying infrastructure is covered in MLOps infrastructure: what you need and when.
Tooling gaps that cause trouble once models are live
Data that changes after deployment needs monitoring of its own. Eken et al. note that operations teams must add telemetry specifically to catch concept drift and safety violations. A 2021 interview study of collaboration in ML-enabled systems points to training-serving skew and data drift as the reasons online evaluation matters, yet found that most organisations in the study did not perform monitoring or online testing. Organisations in that study that had built monitoring and experimentation infrastructure endorsed it strongly.
Sculley et al. describe, among others, these two gaps. The first is “pipeline jungles”: data preparation built up step by step into a tangle of scrapes, joins and intermediate files, where finding errors and recovering from failures is hard and costly. The second is unstable data dependencies, where an “improvement” to an input signal owned by another team can harm the consuming model in ways that are costly to diagnose. Google’s guidance handles one part of this with automated data validation: when input data breaks the expected schema, the pipeline stops so the data science team can investigate. The point for tool selection is that a stack without data validation and drift monitoring is missing the components most likely to matter.
Adopting a platform does not make models reliable on its own
Even in an automated pipeline, some decisions stay with the team. Google’s guidance states that data analysis and model analysis remain manual work for data scientists even in an automated pipeline. Eken et al. warn that full automation can do harm where human judgement is needed, such as model validation that requires regulatory approval, fairness and bias analysis, and root-cause analysis of monitoring alerts.
The rest of the gap is about people. Kreuzberger et al. describe the ML or MLOps engineer as a cross-domain role that builds and operates the ML infrastructure, manages the automated pipelines and deployment, and monitors both models and infrastructure. The 2021 interview study found model teams whose responsibility ended at handing over a model evaluated for accuracy, with no ownership of integration or production testing. Its authors also argue that many organisations underestimate the engineering effort needed to turn a model into a product that can be operated reliably. Shankar et al. (2022) name velocity, validation and versioning as the three variables that govern production success in their interviews. Tools support all three, but none of them supplies the three on its own.
Domain knowledge stays with the team, not the vendor. MLAIA argues that the teams that weathered vendor consolidation best were those with the deepest knowledge of their problem domain, and describes MLOps tooling as “a vehicle for that expertise, not a substitute for it”. In practice, your evaluation framework, your monitoring thresholds and your definition of a bad prediction are what make any platform useful, and they stay with you whichever platform you pick.
When a team wants that engineering work done alongside it, TechnoLynx describes its approach on its MLOps engineering page. Deciding when to engage MLOps consulting and how to avoid dependency is covered separately. Before signing for any platform, settle one question: who on your team will own the drift thresholds and the retraining decision when the dashboard turns red? A tool can raise the alert but cannot make that call.
FAQ
What software is used for machine learning?
Models are usually built in frameworks such as PyTorch. On the MLOps side, the 2026 systematic review of MLOps tools found that four tools stand out across the primary studies: MLflow, DVC, Kubeflow Pipelines and AWS SageMaker, the first three open-source and SageMaker a proprietary cloud service. A broader introduction to MLOps tools and frameworks explains where each one fits.