For many organisations with successful AI programs, in house vs outsource for AI is not a choice between two teams. It is a split of activities: keep problem definition, data governance, model acceptance and production integration inside, and buy data pipelines, model training, MLOps and proof-of-concept work from specialists. That split only builds capability if the outsourced work comes back to your team. In practice that means a phased engagement with a gate between phases, knowledge transfer your own engineers can demonstrate, and a record of each decision you can defend at review.
The rest of this article covers where that line sits, what the evidence says about partnering versus building alone, and how to structure an engagement so it leaves capability behind rather than dependency.
In house vs outsource, activity by activity
The table below is the default split. It is a starting position to argue from, not a rule. Each row says who should own an activity and why.
| Activity | Default owner | Reason |
|---|---|---|
| Problem definition and success criteria | In-house | It requires business context only the organisation holds. |
| Data access and governance | In-house | Security and compliance must stay internal. |
| Model evaluation and acceptance | In-house | It is a business judgement, not technical work. |
| Production integration | In-house | It is tightly coupled to your own systems. |
| Tool ownership and admin rights | In-house | Data platforms and tools sit under enterprise subscriptions with admin rights held internally, while vendors execute. |
| Architecture standards | In-house lead | An internal lead approves tool selection, reviews data models and enforces documentation standards. |
| Data pipelines and model training | Outsource | Listed as safe to outsource in vendor guidance. |
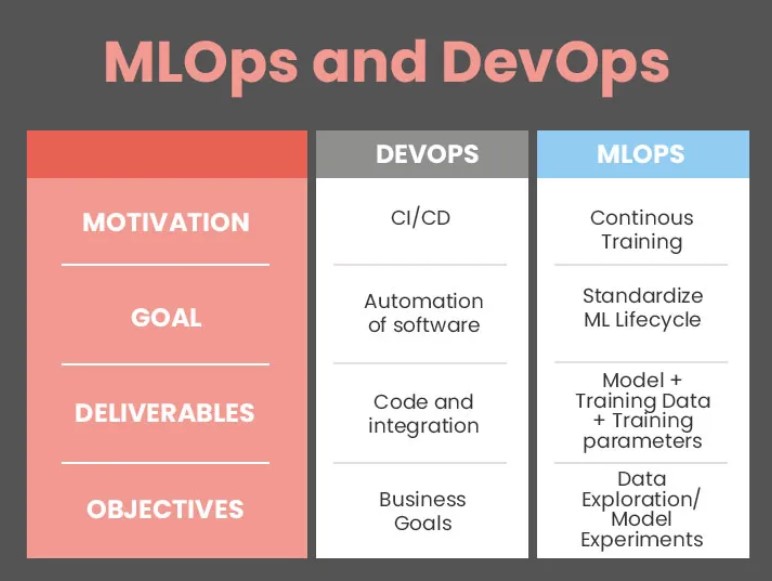
| MLOps | Outsource, built in from sprint one | When MLOps is an afterthought, the model-to-production gap becomes the most expensive part of the project. |
| Proof-of-concept work | Outsource | Outsource when use-case validation is the priority. |
| Monitoring and retraining | Co-own | Ownership moves to the internal team over time. |
| Occasional niche skills | Outsource | Some niche skills are needed too rarely to keep on staff permanently. |
Most rows in that table come from one vendor’s guidance, so it is fair to ask whether neutral sources agree. In direction, they do. The US General Services Administration’s AI guide warns that wholesale outsourcing of core capabilities to contractor personnel teams “creates major operating risk” to core functions. The UK Cabinet Office’s Consultancy Playbook (2022) says external consultants should fill specific capability gaps, not capacity shortages, which it says contingent labour handles better.
That capability-versus-capacity distinction is the most useful test we know for any line in the table. If you are buying a skill you lack, outsource it, with a plan for it to come back or to stay external on purpose. If you are buying extra hands while keeping technical direction, you are renting capacity, and the risk stays with you. How teams slide into that by default is covered in our piece on hiring AI engineers: roles, cost and interview gaps.
Specialist work is easiest to place when it is concrete. Running hyperparameter sweeps at scale, or S-LoRA multi-adapter serving for many fine-tuned variants, are examples of specialist work a team can buy rather than build. A bounded use case such as sentiment analysis in production is another, because the scope is fixed and the system can be handed over once it runs.
“Won’t building it ourselves give us better odds?”
The MIT evidence points the other way, at least for getting a first system into use. MIT NANDA’s State of AI in Business 2025 found that external partnerships with learning-capable, customised tools reached deployment about 67% of the time, against about 33% for tools built internally. The report bases this on a review of more than 300 public AI initiatives, 52 structured interviews and 153 survey responses from senior leaders. It defines success as deployment beyond the pilot phase with measurable KPIs.
The limits matter, and the report states them itself: the figures are self-reported and may not account for all confounding variables. The study compares bought or partnered generative AI tools with internal builds, not outsourced custom development of every kind of machine learning system. It also measures whether something reached deployment, not whether the organisation can run and extend it afterwards.
Public-sector guidance seems at first to pull the other way. The UK National Audit Office (2025) says public bodies should start from the assumption that their own staff are the best use of resources. The GSA says agencies should build sustainable institutional AI capability that does not lean too heavily on vendors.
These sources are answering different questions, so they do not really conflict. MIT measures whether a pilot reaches deployment beyond the pilot phase. NAO and GSA care about sustainable internal capability and the ability to perform core functions. Read together, they support the hybrid in the table: partner to ship, and own what you need to keep running. Andrew Ng’s AI Transformation Playbook makes the same point: outsourced partners can build early momentum faster, while in the long run some projects are better run by an in-house team that builds a unique advantage.
What in-house costs before the first model ships
In the US, the Bureau of Labor Statistics puts median pay for data scientists at $120,230 in May 2025, and projects employment growth of 35% from 2025 to 2035. Nash Squared and Harvey Nash report that hiring and developing talent is the biggest roadblock to success for organisations scaling AI.
The figures below come from AI consulting firms such as AIDOLS, which sell the alternative. AIDOLS cites $30,000 to $50,000 in recruiting cost per hire and three to six months of ramp-up before full productivity. Alice Labs puts a lean in-house team at €600,000 to €900,000 a year before recruitment.
Alice Labs also describes a minimum viable in-house team of three to five people:
- one or two ML engineers for model development, fine-tuning and productionisation;
- one data scientist for experimentation, feature engineering and evaluation;
- one data engineer for pipeline architecture, data quality and platform reliability;
- one AI product manager for use-case prioritisation and roadmap ownership;
- an emerging AI governance lead role for compliance and risk monitoring.
Team size should match the stage of the work rather than borrowed benchmarks: eight people slow down a proof of concept, and two people maintaining twelve production models are overwhelmed. Which of those roles to staff first, and how the full cost comparison works out, are covered in depth in our guide to data team structure for AI projects.
A three-phase engagement with a gate between each phase
The outsourced share works best as three phases with an explicit go or no-go decision between each. Discovery and proof of concept are billed on time and materials. Development runs on milestones or with a dedicated team. A transition phase then moves operational ownership to your engineers before the vendor leaves.
The transition phase needs its own budget rather than being a rounding error at the end. Saigon Technology describes it as documentation, knowledge transfer sessions, pair programming, and a supervised period in which your team runs the system while the vendor is still available. Skip it and you end up with a production system nobody on your team can maintain.
Across projects, the same vendor proposes a sequence. Outsource the first project entirely while hiring your first ML engineer. That engineer co-develops the second project, and by the third your team runs on its own. Alice Labs puts this kind of evolution, from consulting-led pilots to hybrid to partial in-house, at three to five years for most enterprise AI strategies. We treat both timelines as rough guides rather than plans: the pace depends on how fast you can hire, and on whether the first system was built to be inherited. How the decision itself changes with maturity is set out in the build-or-hire decision framework.
Knowledge transfer you can test before the vendor leaves
Knowledge transfer is not a deliverable to trim in scope negotiations. It is how the engagement leaves capability behind. Alice Labs lists four mechanisms:
- Documented architecture decisions, recording why each model and design choice was made, not only what was built.
- Runbooks and operational documentation detailed enough for an internal team to operate and iterate on the system.
- Hands-on training sessions covering the tools, patterns and decision logic used.
- A handover sprint of two to four weeks, with the consultants working alongside your team before stepping back.
Two working conditions make those mechanisms real. First, the vendor works in your repositories, CI/CD pipeline and experiment tracking from day one, so nothing has to be “delivered” in batches at the end. Second, your people are committed to a blended team. The Cabinet Office warns that without internal resource, knowledge transfer becomes less effective. The playbook also calls knowledge transfer a dynamic process, not a handover of static documents.
The proof is a test, not a document. Before the transition phase ends, ask your engineers to run a supervised model retrain and a debugging exercise on their own. If they cannot retrain, debug and extend the system, you have created a dependency, not a capability. Alice Labs recommends a structured handover sprint with explicit internal capability sign-off before engagement close, built in at the RFP stage rather than after signature.
Who can build the outsourced part and hand it back?
TechnoLynx builds specialist parts of an AI system, such as GPU-accelerated inference, computer vision, generative AI and production monitoring. The engagement is shaped around named risk, outcome ownership rather than rented capacity, and packageable artefacts at each milestone. TechnoLynx lists its engagement routes on its services page. What a consultant engagement should contain, how to price it and what to accept as exit criteria are covered in what an LLM consultant delivers and how to scope it.
This model does not suit everyone. If AI is your core product, vendor guidance says build in-house, and the GSA’s AI guide warns against wholesale outsourcing of core capabilities. If you need extra hands under your own technical lead, contingent labour is the better-suited route. For a commoditised task, an off-the-shelf tool may be enough, with no engineering engagement at all.
Signs an engagement is building dependency
Run this checklist at every gate, not only at exit. Our guide to data team structure for AI projects treats dependency patterns in full.
- The vendor, not you, owns or controls the models, infrastructure or data stores.
- Admin rights and tool licences sit with the vendor.
- Logic, metric definitions and business rules live outside your shared repositories.
- The contract has no clauses for asset ownership, documentation delivery or transition support.
- Ownership of fine-tuned weights, embeddings and prompt libraries at the end of the engagement is undefined.
- No internal engineer understands the system well enough to keep it running if the vendor leaves.
- The same task keeps going back to external consultants.
Making each milestone defensible
When an AI initiative fails, accountability does not disappear into the model. It falls on whoever chose the vendor, signed the scope and defended the decisions internally. That is why engagement structure matters beyond delivery. At any review, the buyer should be able to show what was known, what was scoped, what the milestone produced and how each decision was made.
Several sources name artefacts that build this record. One is an architecture decision record from discovery, explaining why each choice was made so you are never locked into decisions you do not understand. Another is a set of defined outcomes, measures and timelines with built-in review points. A third is reviews of data quality, model performance on key segments and infrastructure cost, rather than sprint demos alone, because a model can look good in a demo and fail quietly in production. With these artefacts, the go or no-go decision at each gate becomes a documented judgement rather than a matter of momentum.