Mixed precision training works because numerical sensitivity is spread unevenly across a neural network. The matrix multiplications and convolutions that do most of the compute tolerate 16-bit inputs, while a short list of operations needs FP32. NVIDIA’s training guide puts it this way: identify the steps that need full precision, run only those in 32-bit floating point, and use 16-bit everywhere else. Those steps include large reductions, softmax and batch-normalisation statistics, and some networks also need an FP32 weight copy.
Stability comes from choosing which few computations keep their bits.
Why a Matmul Can Run in 16 Bits and Still Give the Right Answer
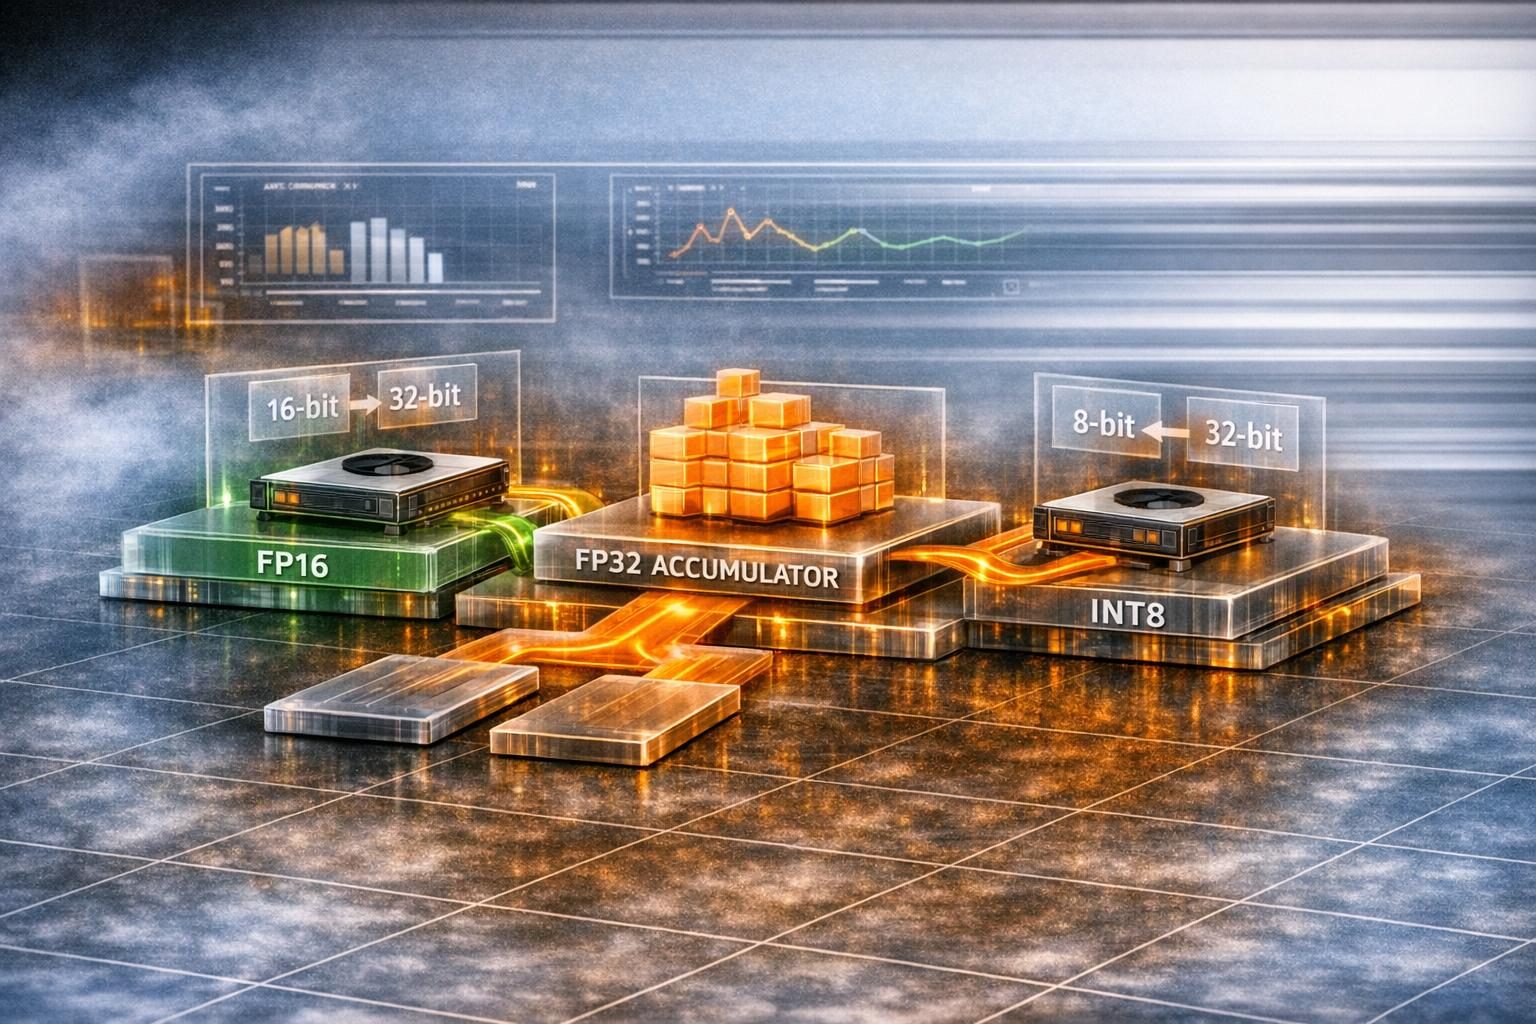
Google’s Cloud TPU team stated the intuition in its bfloat16 write-up: for the overwhelming majority of computations in a deep network, a lower-precision approximation reaches the same accuracy as computing every digit. The hardware splits each multiply-accumulate across two precisions. On NVIDIA Tensor Cores the input matrices are half precision, and the accumulator and output can be single precision. On Google’s TPUs each multiply uses bfloat16 and each accumulation uses 32-bit IEEE floating point.
That split carries a lot of weight. The original NVIDIA mixed precision work found that accumulating into single precision was critical to good training results, and accumulated values were converted to half precision only when written to memory.
The cost of the bargain can be measured. A 2024 rounding-error analysis of mixed-precision fused multiply-accumulate found error nearly four orders of magnitude larger than full-precision FMA, for close to a twofold performance gain. The same paper explains why worst-case estimates overstate the error. Worst-case deterministic bounds badly overestimate accumulated error for large low-precision problems, while probabilistic bounds, which let rounding errors cancel, grow with the square root of the operation count.
Those bounds treat rounding errors as independent random variables. The flash-attention case further down shows rounding errors that build up in one direction instead of cancelling.
Which Operations Break in 16 Bits and Need Full Precision
The exceptions are listed in NVIDIA’s mixed precision guide. Values computed by large reductions should stay in FP32, with batch-normalisation mean and variance and softmax as the named examples, and some networks also need an FP32 copy of the weights. TensorFlow’s mixed precision guide likewise asks for a float32 softmax and a float32 model output.
A reduction sums many terms, so its rounding error bound grows with the operation count. Softmax and other exponentials turn moderate inputs into values that overflow a narrow format. NVIDIA’s automatic mixed precision puts large reductions, cross-entropy loss, L1 loss and exponentials on its DenyList for that reason. It also treats ops such as Exp and Log as ones whose outputs are not safe to cast back to FP16.
The weight update fails in a different way. Weight gradients, after multiplication by the learning rate, are often much smaller than the weights they adjust. In half precision the smaller addend can shift to zero when the binary points are aligned, so no update happens at all. The fix is to keep a single-precision master copy that receives the updates, while the forward and backward passes use a half-precision copy.
Optimizer state splits again. FP8-LM (Microsoft, 2023) found that Adam’s first moment tolerates FP8 with tensor scaling, but the second moment needs 16-bit precision, because squaring small gradients underflows. A 2025 convergence analysis gives the theoretical reason: second-moment errors are amplified non-linearly by the inverse square root in the update step. DeepSeek-V3 (2024) tracked both AdamW moments in BF16 without observable degradation, but kept master weights and accumulated gradients in FP32.
Where Each Part of a Training Step Usually Sits
| Computation | Typical precision | Why |
|---|---|---|
| Matmul and convolution inputs | FP16 or BF16 (FP8 with scaling) | On the AllowList; they benefit from Tensor Cores |
| Matmul accumulation | FP32 | Accumulating into single precision was critical to training results |
| Large reductions, batch-norm statistics | FP32 | Values from large reductions should stay in FP32 |
| Softmax, Exp, Log, cross-entropy | FP32 | May overflow FP16 or need FP32 precision |
| Element-wise ops with mixed inputs | Widest input type | AMP casts to match the widest input |
| Master weights | FP32 | Small updates vanish in half precision |
| Adam first moment | Can go as low as FP8 with scaling | Tolerates high quantisation error |
| Adam second moment | 16-bit or higher | Squaring small gradients underflows |
BF16 vs FP16: Range Against Precision
Choosing between BF16 and FP16 means choosing between dynamic range and precision. Google designed bfloat16 knowing that neural networks are far more sensitive to the size of the exponent than to the size of the mantissa.
IEEE 754 half precision has 1 sign bit, 5 exponent bits and 10 fraction bits. Its normalised values run from 2^-14 up to a maximum of 65,504, denormals reach down to about 5.96e-8, and the full span including denormals covers 40 powers of 2. Single precision covers 264 powers of 2. BF16 uses 1 sign, 8 exponent and 7 mantissa bits, so its dynamic range is identical to FP32’s.
Training studies confirm the greater sensitivity to exponent bits. The 2024 study “To FP8 and Back Again” found that removing even a single exponent bit across all layers prevented Llama models from training at all. Kalamkar et al. (2019) showed BF16 matching FP32 results in the same number of iterations without hyperparameter changes, while FP16 needs hyperparameter tuning. Models above 100 billion parameters, such as Bloom and OPT, struggled to find a stable FP16 loss scale and moved to BF16.
Precision still counts for some models. Gopher reported that BF16 degraded performance against FP32 even with stochastic rounding, which Perez et al. (2023) attribute to its smaller mantissa. PyTorch’s guidance follows from this: a network that needs more precision may need FP16, one that needs more range may need BF16, and if overflows appear, try BF16 first. Moving a model between formats carries its own risk. PyTorch warns that most BF16-pretrained models cannot operate inside FP16’s 65,504 ceiling, so their gradients overflow, and recommends fine-tuning such models in BF16.
FP16’s narrow range is also why it needs loss scaling. In NVIDIA’s analysis of the Multibox SSD detector, 31% of activation gradient values became zero when converted to FP16 and the network diverged, while shifting them by three exponent values (a scale of 8) matched FP32 accuracy. Dynamic loss scaling automates the choice of scale. It starts with a high scale such as 2^24 and checks the gradients for infs or NaNs at every iteration. When there is no overflow it unscales the gradients in FP32 and applies the update. When there is an overflow it skips the update and reduces the scale, by a factor of 2 by default. After a run of clean iterations it raises the scale again.
Why Can’t torch.autocast Catch Every Risky Operation?
torch.autocast cannot catch every risky operation because it decides from op lists, and anything off those lists is assumed safe. PyTorch’s reference says that if an op is unlisted, it is assumed to be numerically stable in bfloat16, and float16 shares those lists. The AMP recipe adds that explicit coverage is chosen from numerical properties but also from experience, and that a type-mismatch error in an autocast region may mean autocast missed an op.
Some known cases are blocked outright. The backward pass of binary cross-entropy can produce gradients that FP16 cannot represent, and casting the forward input up to FP32 does not help because the cast is reversed in backward, so binary_cross_entropy and BCELoss raise an error inside autocast regions. PyTorch also recommends disabling autocast first around torch.linalg operations and around pre- and post-processing, which are often especially sensitive.
One study traced a loss explosion in BF16 flash attention training to biased rounding in the unnormalised attention output, the product of the unnormalised probabilities and V. When a row of pre-softmax scores contains several identical maxima, the matching probabilities become exactly 1. Adding pairs of negative BF16 values then rounds consistently in one direction. The errors accumulate across training steps instead of cancelling. Computing only that one product in FP32 was enough to stabilise training. The behaviour was consistent across NVIDIA A100, RTX 4090 and Huawei Ascend 910B hardware. The same paper cites Lee et al. (2024): roughly 10% of GPT-2 pretraining runs diverged under pure BF16, against none under TF32.
Debugging such a case takes local tools. Hugging Face Transformers provides a detector that reports the first frame where inf or nan appears under FP16 mixed precision, and shows how to disable autocast for one module’s forward pass. Autocast should wrap only the forward pass and loss, because backward ops run in whatever type autocast chose for the matching forward op.
What FP8 Needs Beyond 16-Bit Mixed Precision
FP8 keeps the same tolerance argument but needs scaling, two encodings and higher-precision accumulation.
The 2022 FP8 formats paper defines two encodings: E4M3 (4 exponent bits, 3 mantissa bits) and E5M2 (5 exponent bits, 2 mantissa bits). It recommends E4M3 for weights and activations and E5M2 for gradients. Gradients need the range of five exponent bits, while activations and weights need at least three mantissa bits.
FP8 matrix multiplications need scaling factors to prevent underflow and overflow in both the forward and backward passes. Some networks need per-tensor factors because FP8’s range cannot cover the important values of every tensor at once, and the need grows as more tensors are stored in FP8. FP16’s habit of skipping updates on overflow does not carry over, because FP8 overflows far more often and too many updates would be skipped.
Accumulation must stay wider than the inputs. FP8 matmuls accumulate in FP16, BF16 or FP32, and accumulating in FP8 would fail on E4M3’s range or E5M2’s precision. Hardware accumulation can also be narrower than FP32. DeepSeek-V3’s report observes that FP8 GEMM accumulation on NVIDIA H800 GPUs retains only around 14 bits. Its workaround copies partial results to FP32 registers on CUDA cores every 128 elements.
More of the model stays at high precision too. DeepSeek-V3 kept the embedding module, output head, MoE gating, normalisation and attention in BF16 or FP32. Perez et al. (2023) quantised only the decoder’s linear layers, which account for more than 99.9% of decoder compute in a model like Llama 2 70B, and kept dot-product attention in higher precision. Some failures appear only late. Fishman et al. (2024) found instabilities in trillion-token FP8 runs, traced to SwiGLU outlier amplification over prolonged training.
Published results differ on whether FP8 training is worth it. “To FP8 and Back Again” (2024) found non-trivial degradation with MS-AMP and called FP8 training in its current form uneconomical, not impractical. FP8-LM reported loss curves matching BF16 across model scales, and Fishman et al. reported parity with a BF16 baseline and up to about 34% higher throughput on Intel Gaudi2.
Why Is Mixed Precision Sometimes No Faster, or Even Slower?
Mixed precision speeds up only the parts of a training run that a faster low-precision path accelerates, so the end-to-end gain is smaller than the peak figures. NVIDIA works the arithmetic through: if half the training time is in Tensor Core operations and those run 5x faster, the total speed-up is 1 / (0.5 + 0.5/5) = 1.67x.
Several other limits cut into the gain:
- Memory-bound kernels. On a V100 (125 TFLOPs, 900 GB/s), any kernel below about 140 FLOPs per input byte is limited by bandwidth, not by Tensor Core throughput.
- Shape constraints. Tensor Cores need FP16 matmul dimensions in multiples of 8.
- Hardware generation. Among NVIDIA GPUs, those with compute capability 7.0 or higher gain most, because they have Tensor Cores.
- Stabilisation in software. In FP8 training, stochastic rounding and Kahan summation implemented in software cancel out the gains of reduced precision, because current NVIDIA GPUs do not support them natively.
- Data movement. Shuttling partial results between Tensor Cores and CUDA cores still limits computational efficiency in DeepSeek-V3’s FP8 scheme.
LynxBenchAI binds every result to the whole stack, not to the chip alone. In the 26Q3 results, the NVIDIA GeForce RTX 3080 scores 71.2 on FP16 dense matmul under native Linux, while the same card under WSL scores 106.2, with FP32 at 109.6 and 112.2 respectively. On the NVIDIA L40S, FP16 dense matmul scores 243.7 against 303.0 for FP32, while the NVIDIA H100 80GB HBM3 scores 1264.3 for FP16 against 1026.7 for FP32. FP8 inference produced no result (0.0) on the NVIDIA A100-SXM4-80GB in the same release. Each score comes from a test at one fixed precision, not a mixed-precision run, and the release does not record why FP16 trails FP32 on some stacks.
How LynxBenchAI Measures Precision
LynxBenchAI treats numerical precision as a first-class design trade-off. It runs each model across several precisions (FP64, FP32, FP16 and BF16 on compute; FP32 and BF16 on training; FP16, INT8 and FP8 on inference), reports each separately, and enforces a per-precision correctness threshold before a result counts.
Because each test holds its recipe fixed, the results give separable per-precision endpoints, not a verdict on any other mix of formats. Every endpoint belongs to an AI Executor: the device plus the backend, driver, framework and runtime it ran with. The RTX 3080 pair above is an example. Scores compare within the 26Q3 release only. A selective-precision design of your own still has to be measured on your model, which is the gap described in inference benchmark vs workload evaluation. What the Personal Edition gives you is the baseline on your own machine that such a design has to beat. It installs with pip install lynxbench-ai.
Turning a Mixed Scheme into Something You Can Ship
Moving a production model from an all-FP32 path to selective retention is a GPU performance engineering change that someone has to validate on one specific stack, and the RTX 3080 entries show one card scoring differently under native Linux and WSL. TechnoLynx’s AI porting and deployment pack is where that viability question stops being a hypothesis, and what a performance and porting assessment actually delivers sets out the output. Running the validated model in production afterwards falls under MLOps engineering.
FAQ
What Does FP16 Stand For?
FP16 is 16-bit floating point, the IEEE 754 half-precision format with 1 sign bit, 5 exponent bits and 10 fraction bits.
What Is the Range of FP8?
E5M2 provides 32 binades of dynamic range including subnormals. E4M3 would have 17 binades under IEEE conventions, but extends its range by not representing infinities and using fewer special-value encodings.