A 16-bit float in the IEEE sense (FP16, binary16) stores a number in 1 sign bit, 5 exponent bits and 10 fraction bits, which caps its magnitude at 65,504 and flushes anything smaller than about 2^-24 to zero. That range is narrower than FP32’s, so FP16 can overflow large values to infinity, and training in it relies on techniques such as an FP32 master copy of weights and loss scaling to avoid accuracy loss. Not every operation needs the same precision, and mixed precision works because it spends precision unevenly, where the numerics demand it.
The 16-bit float layout and where its range runs out
The IEEE 754 half-precision format encodes the exponent with a bias of 15, giving normalised exponents from -14 to 15, with exponent codes 0 and 31 reserved for special values. Counting subnormals, non-zero magnitudes span roughly 2^-24 to 65,504. Near 1.0 the format is coarse too: the smallest value above 1 is 1 + 1/1024.
FP32 and BF16 both use an 8-bit exponent, which is why their range is so much wider than FP16’s. The appeal of FP16 is elsewhere: half the bytes per value means less memory and faster transfers, and hardware with native half-precision instructions often runs it faster than single or double precision.
The two ends of the range fail differently. At the bottom, the ICLR 2018 mixed-precision paper (Micikevicius et al.) found that weight updates smaller than 2^-24 become zero in FP16, and that roughly 5% of weight-gradient values in one of its networks had exponents below -24. At the top, NVIDIA’s TensorRT documentation notes that overflow past 65,504 produces Inf, which can propagate into NaN and wreck model accuracy. Large-magnitude values also carry a large unit in the last place, so rounding error grows with the value and can accumulate into instability.
How mixed precision keeps FP16 stable
NVIDIA describes three techniques that make FP16 training work: accumulating FP16 products into FP32, scaling the loss so gradients do not underflow, and keeping an FP32 master copy of the weights for updates.
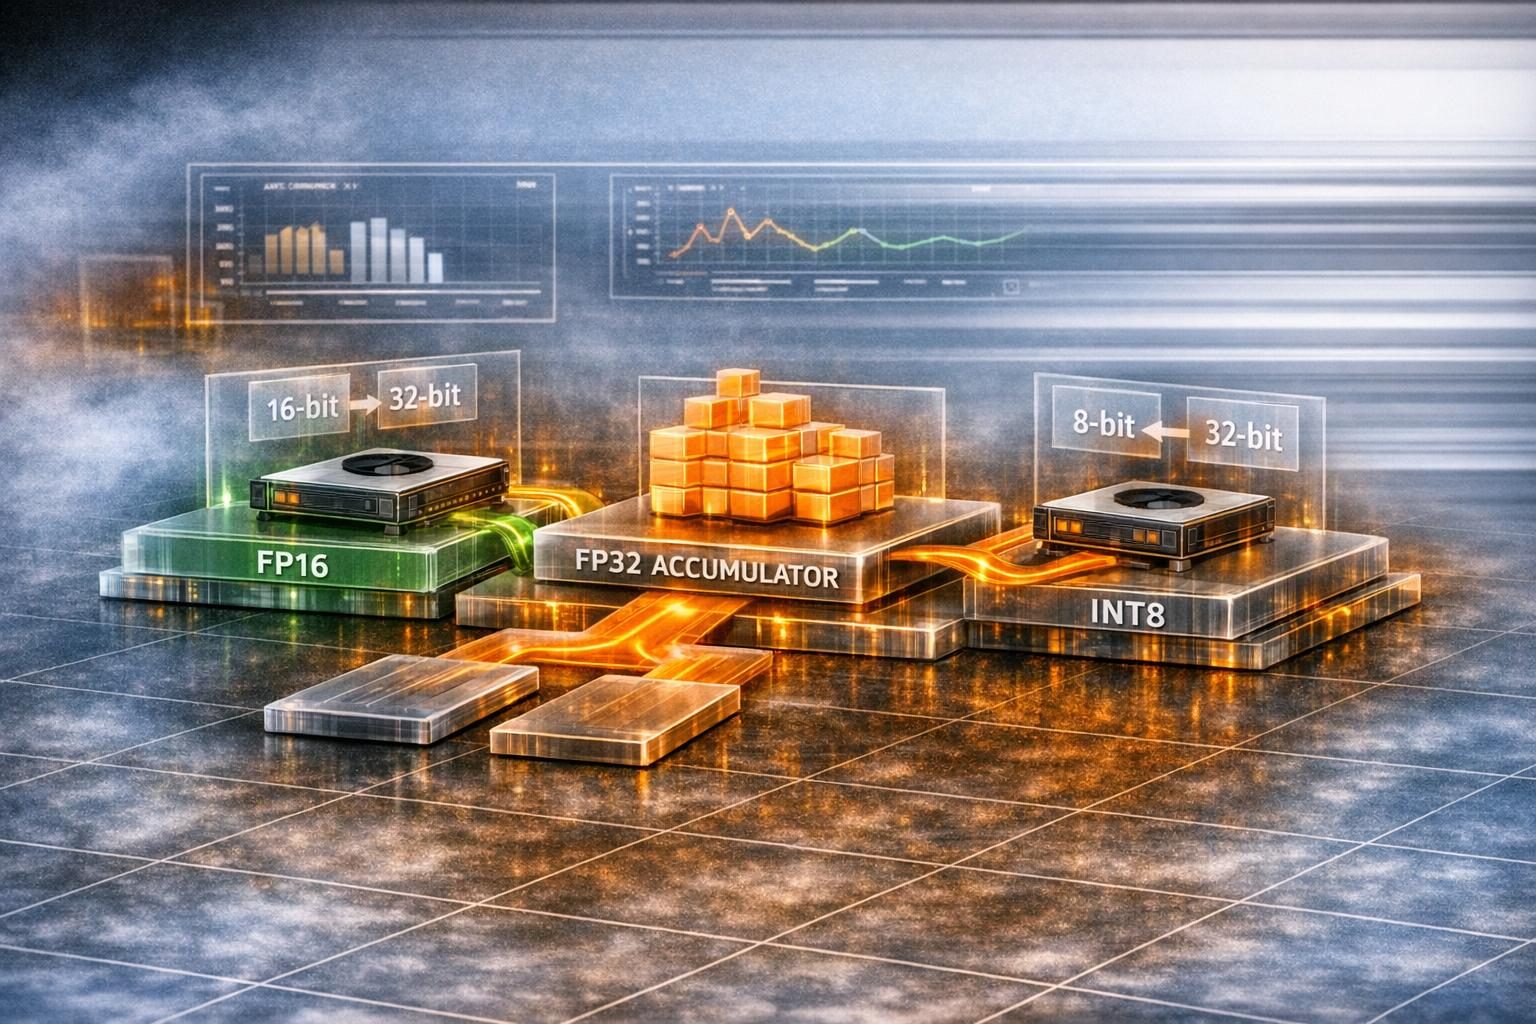
The master copy exists because weight updates can be too small to represent in FP16. In the ICLR 2018 scheme, weights, activations and gradients are stored in FP16 for the forward and backward pass, while an FP32 copy of the weights takes the optimiser step, so updates that would round to zero in FP16 still land. FP32 accumulation matters for dot products: the same paper reports that some FP16 models matched their baselines only when partial products were summed into FP32 before being written back as FP16. Large reductions, mostly in batch normalisation statistics and softmax, are also done in FP32 arithmetic while the tensors stay FP16 in memory, which the authors found did not slow training because those layers are bandwidth-bound.
Attention shows the same unevenness inside one block: query-key dot products, then softmax, then the value projection. Our longer argument on why mixed precision works by exploiting numerical tolerance walks through that asymmetry in detail.
Where higher precision is usually retained
| Operation | Typical precision in a mixed scheme | Why |
|---|---|---|
| Convolutions, fully connected layers, matrix multiplies | FP16 inputs, FP32 accumulation | Tensor Cores accelerate them; summing partial products in FP16 loses accuracy in some models |
| Weight update (optimiser step) | FP32 master weights | Updates below 2^-24 vanish in FP16 |
| Softmax | FP32 | NVIDIA’s guidance keeps softmax in float32 |
| Large reductions, batch-norm statistics | FP32 arithmetic, FP16 storage | Sums across many elements need the range and precision |
| Cross-entropy loss, L1 loss, exponentials | FP32 | NVIDIA’s AMP deny list: may overflow FP16 or need FP32 precision |
| Element-wise add, multiply by a constant | Either | Safe in FP16 or FP32 (NVIDIA’s infer list) |
| Bias tensors (BF16 study) | FP32 | Kept in full precision in the BF16 study’s training flow |
Which networks still diverge or drift under mixed precision?
Mixed precision does not stabilise every network the same way: some need loss scaling and others do not. In the ICLR 2018 experiments, some networks needed no loss scaling, while the Multibox SSD detector diverged without it and needed a scale factor of 8. A large LSTM language model needed a factor of 128, and its FP16 training perplexity diverged from the FP32 run after 300K iterations without it. The 2019 BF16 study notes that recurrent networks have been observed to need more range and to be more sensitive to half precision.
The PyTorch documentation is blunt about it: “AMP/fp16 may not work for every model”. Most models pretrained in BF16 cannot operate within FP16’s 65,504 ceiling, and their gradients overflow instead of underflowing.
A 2025 study of LLM inference (arXiv 2506.09501) found that FP32 is nearly perfectly reproducible across GPU types, GPU counts and batch sizes, FP16 shows moderate variability, and BF16 is substantially unstable. Floating-point addition is not associative, so the order of summation changes results, and BF16’s larger rounding error amplifies it.
Why does an inference-only FP16 setup usually not need loss scaling?
During backpropagation in FP16, small gradients risk becoming zeros, and loss scaling is there to prevent that. The technique multiplies the loss before backpropagation so that, by the chain rule, every gradient is scaled up out of the underflow zone, then the gradients are divided back down before the weight update. Without a backward pass there is nothing for it to act on.
TensorRT’s guidance for mixed-precision inference is to run precision-sensitive calculations in FP32 and use reduced precision for less sensitive operations, with linear layers as the natural FP16 candidates. The FP16 risk that remains is overflow to Inf and NaN, and most BF16-pretrained models cannot operate within FP16’s range. “Usually” here means the problem moves rather than disappears: the inference engineer watches activations for overflow instead of gradients for underflow.
Trading range for resolution: training in BF16 versus FP16
BF16 makes the opposite trade from FP16: an 8-bit exponent and 7-bit mantissa, so it has a wider dynamic range than FP16 but lower precision. The 2019 BF16 study reports that BF16’s FP32-like range lets it avoid loss scaling, and that its experiments ran without any hyper-parameter changes, whereas FP16 needed an additional loss-scaling hyper-parameter.
The cost turns up in the mantissa. In the 2025 reproducibility study, BF16’s 7 mantissa bits produced significantly higher variance in top-1 token probabilities than FP16’s 10 bits, raising the chance of token flips where the top two candidates are close. Under greedy decoding, only 2.2% of samples diverged across runtime configurations in FP32, against over 90% showing divergence in BF16. So BF16 is the easier format to train in and FP16 the more reproducible one in that study, and which matters more depends on whether range or resolution is the binding constraint for the model.
What does automatic mixed precision decide for you, and what still has to be decided by hand?
Per-operation data types are set by the casts that automatic mixed precision inserts, and it also turns on loss scaling in training; PyTorch still tells you to verify model compatibility. In PyTorch, torch.amp autocast regions run each op in an op-specific dtype chosen to improve performance while maintaining accuracy, with linear layers and convolutions in FP16 or BF16 and reductions kept in float32. GradScaler handles gradient scaling during training so small gradients do not flush to zero. NVIDIA’s AMP for TensorFlow inserts the cast operations into the graph and turns on automatic loss scaling inside the optimiser. Dynamic loss scaling starts high (for example 2^24), skips the update and reduces the scale when it sees Inf or NaN, and raises the scale again every 2,000 iterations by default.
PyTorch states that if an op is unlisted, it is assumed numerically stable in float16. Some ops refuse outright: binary_cross_entropy and BCELoss raise an error inside autocast regions because their backward gradients may not be representable in float16.
What stays manual, as a checklist:
- Format compatibility: whether the model’s value range fits FP16 at all, which PyTorch tells users to verify when NaNs appear.
- FP16 or BF16: which lower-precision type autocast should target, since the two fail in different directions.
- Unlisted custom ops: any op the framework assumes stable but your model uses unusually.
- Optimisation level: in NVIDIA’s Apex terms, O1 is the recommended AMP setting, while O2 (everything in FP16) is faster but may not converge to FP32 results.
- Batch size: AMP lowers memory use, so throughput often improves further when the batch size is raised after enabling it.
- Acceptance tolerance: ONNX Runtime’s
auto_convert_mixed_precisiontool finds a minimal set of ops to keep in float32, but you supply thertolandatolit validates against.
The ONNX Runtime tool is a useful picture of what “automatic” means: it converts clusters of ops to float16 and, when a cluster fails validation, splits it in half and tries both halves. It automates the search. The definition of “good enough” is still yours.
Mixed precision is not quantisation
Quantisation maps values onto an integer grid with a scale, whereas mixed precision leaves every value a floating-point number and changes only how many bits it gets. ONNX Runtime’s documentation says float16 conversion may cost some accuracy, and its mixed-precision tool keeps a minimal set of ops in float32. INT8 inference on a network trained in floating point, by contrast, needs post-training quantisation calibration and sometimes quantisation-aware training to hold accuracy. The two often coexist in one deployment, but treating them as the same change hides the calibration step and its failure modes.
Quantising a production model, tuning its kernels or deciding which layers can drop precision on a specific stack is engineering work rather than measurement, and TechnoLynx handles it as part of GPU performance engineering.
FP8 as the next step in mixed precision, and the per-tensor scaling it needs
The 2022 FP8 formats paper from NVIDIA, Arm and Intel treats FP8 as a further step in mixed precision: it expects operations on FP8 inputs to produce higher-precision outputs, as already happens with FP16 and BF16. It defines two encodings, E4M3 recommended for weights and activations and E5M2 for gradients, and some networks need both. E5M2 follows IEEE conventions and can be viewed as FP16 with fewer mantissa bits, while E4M3 reclaims special-value bit patterns to extend its range.
The extra assumption is about scaling. FP8’s range is too narrow to cover all tensors’ important values, so some networks need a scaling factor per tensor, chosen so the tensor’s maximum lands near the format’s maximum, with overflows saturated. The paper also rejects FP16’s dynamic-loss-scaling habit of skipping updates on overflow, because overflows are much more likely in FP8 and too many updates would be skipped. In one language model, quantising residual connections to FP8 left no single exponent bias with acceptable accuracy. The paper’s own position is that inference also gets simpler when a network is trained in FP8, since training and inference then share data types.
FP8 results also depend on the executor. In the 26Q3 results, FP8 inference produced no result (a recorded 0.0) on the NVIDIA A100-SXM4-80GB, the NVIDIA GeForce RTX 3090 and the NVIDIA GeForce RTX 3080, across all four FP8 inference models. On the NVIDIA H100 80GB HBM3, FP8 scored below FP16 on every FP8 inference model in 26Q3, for example 1362.7 against 2611.7 on DistilBERT. A lower format does not automatically buy a higher score, and the regime differences are set out in how FP8, FP16 and BF16 represent different operating regimes.
Can a LynxBenchAI FP16 result be read as a mixed-precision measurement?
No: each LynxBenchAI test runs at one fixed precision, not a mixed-precision design you might build. LynxBenchAI runs each model at a set of precisions (fp64, fp32, fp16 and bf16 on compute, fp32 and bf16 on training, fp16, int8 and fp8 on inference) and reports each separately. Keeping the levels separate is deliberate, because it is what leaves clean endpoints a mixed scheme can be argued against.
Three further rules shape what a 16-bit figure means, and the LynxBenchAI methodology gives each in full:
- A correctness gate, not an accuracy score. A result counts only if it passes a per-precision correctness threshold, enforced separately for each precision. Given how much more BF16 diverges than FP32 in the reproducibility study above, a single tolerance shared by every precision would either fail BF16 everywhere or wave through sloppy FP32.
- Measured at saturation. Model and precision stay fixed while batch size rises until throughput plateaus within a noise band, so each device is measured at its own saturation point. That matters for 16-bit formats in particular: PyTorch’s AMP recipe notes that mixed precision gives its greatest speedup when the GPU is saturated.
- Bound to the AI Executor. Every result belongs to the device, its backend, and the driver, framework and runtime on that machine, never to the silicon alone. In the 26Q3 results, the same RTX 3080 scored 71.2 on FP16 dense matrix multiply under native Linux and 106.2 under WSL. The release records the difference without attributing it to a cause, and each test is one timed window after a discarded warm-up, not a median of repeats.
Two reading rules follow. Scores compare only within a release, so a 26Q3 FP16 endpoint is never set against one from another release, and the GT aggregate is ordinal, never read as a percentage. A tolerance seen on one stack is a property of that executor too, which is why the result never says FP16 “works” on a chip in general.
If you are choosing hardware and want the endpoints for your own machine, the LynxBenchAI Personal Edition installs with pip install lynxbench-ai. It measures the release’s model catalogue at each precision on your executor; it does not run your model or measure your task accuracy. The gap between those two things is the subject of inference benchmark versus workload evaluation.
Proving a mix on the stack you will ship
A mixed-precision scheme still has to be measured on the specific executor it will ship on. The per-precision endpoints are the baseline your composition has to beat, and it still has to pass your own accuracy checks. Where that proof has to be made on a stack you are moving to, a performance and porting assessment is where the viability of the mix is tested rather than assumed. For whether the precision drop is worth taking at all, our piece on when lower precision’s cost savings are worth the risk weighs the other side.