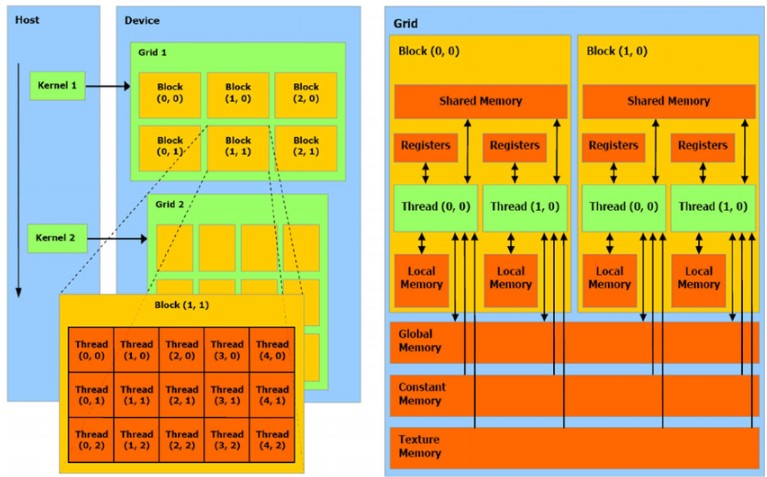
A video card is CUDA compatible when it is an NVIDIA GPU whose compute capability (the major.minor feature level NVIDIA assigns to each architecture) is covered by the code your application ships, and when the installed driver is compatible with the CUDA Toolkit that built that application. Both conditions have to hold. Whether a card will run a given application depends on three version numbers, not one: the card’s compute capability, the toolkit version and the driver version.
Compute capability is the GPU’s hardware feature level
NVIDIA’s CUDA Programming Guide says every NVIDIA GPU has a Compute Capability (CC) number, which indicates what features the GPU supports and specifies some of its hardware parameters. NVIDIA’s own GPU list describes it the same way: compute capability defines the hardware features and supported instructions for each GPU architecture.
The number is written X.Y, where X is the major version and Y the minor version, so CC 12.0 has major version 12 and minor version 0. Familiar values include 7.5, 8.0, 8.6 and 9.0, and each tells the software stack which instructions, precision formats and tensor-core operations the target hardware offers.
The distinction that clears up most confusion is this one. CUDA is the programming model and platform, and compute capability is how that platform shows up in hardware. The CUDA Toolkit is the versioned SDK you install and pin (nvcc, the runtime, cuBLAS, headers), and the driver is a third layer between them. The GPU has the compute capability, and compatibility runs between GPUs, drivers and CUDA Toolkit versions.
Which video cards are CUDA compatible, and how do I check mine?
CUDA is NVIDIA’s platform, so only NVIDIA cards are CUDA compatible in the strict sense. For other vendors’ GPUs the question becomes which compute API to commit to instead, such as OpenCL, SYCL or HIP/ROCm. Whether that switch is worth making is an ecosystem question, and we treat it separately in our piece on CUDA, frameworks and ecosystem lock-in.
For a card that is installed, query it directly. NVIDIA’s Programming Guide gives this command to print GPU names and compute capabilities:
nvidia-smi --query-gpu=name,compute_cap --format=csv
At runtime, the same value comes from the CUDA Runtime API cudaDeviceGetAttribute(), the Driver API cuDeviceGetAttribute() or the NVML call nvmlDeviceGetCudaComputeCapability():
#include <cuda_runtime_api.h>

int major, minor;
cudaDeviceGetAttribute(&major, cudaDevAttrComputeCapabilityMajor, device_id);
cudaDeviceGetAttribute(&minor, cudaDevAttrComputeCapabilityMinor, device_id);
A runtime check like this is worth putting in any service that may land on mixed hardware, because it lets the process refuse to start with a clear error instead of failing on the first kernel launch.
What the compute capability number unlocks
Compute capability is an inventory of features. NVIDIA’s feature table, for example, lists bfloat16-precision floating-point operations as unsupported on 7.x devices and supported from 8.x. How precision support maps to architectures is covered in how precision choices are constrained by hardware architecture.
Most features introduced with an architecture are meant to stay available on all later architectures. Compute Capability 9.0 brought an exception. From 9.0 onwards, NVIDIA introduced architecture-specific compiler targets, selected with an a suffix such as compute_100a or compute_120a, and the specialised features they expose are not guaranteed to exist on later compute capabilities. Code built against an architecture-specific target may therefore not run on later compute capabilities.
For the AI side of this, see our explanation of what the compute capability version number means for AI workloads.
Binary and PTX compatibility: the rules that decide whether code loads
Compiled GPU code in an application comes as a cubin, compiled for a specific compute capability, or as PTX, which is JIT-compiled at application runtime. The rules differ for each.
A cubin runs on its own major version at equal or higher minor versions, and never across major versions; PTX can be JIT-compiled for any equal or higher compute capability.
In NVIDIA’s terms, within a major version, a GPU whose minor version is greater than or equal to the cubin’s target can load and execute it. GPUs are not binary compatible between major versions. PTX stored in the application can be JIT-compiled at runtime for any compute capability equal to or higher than the PTX’s own, which gives forward compatibility with future GPUs without rebuilding.
Worked example: which cards load which build
The cases below come straight from NVIDIA’s examples in the Programming Guide.
| What the application contains | Target GPU CC | Loads? | Why |
|---|---|---|---|
| cubin for 8.6 | 8.6 | Yes | Same major, same minor |
| cubin for 8.6 | 8.9 | Yes | Same major, higher minor |
| cubin for 8.6 | 9.0 | No | Different major version |
| PTX for compute_80 | sm_120 | Yes, via JIT | PTX compiles forward to higher CC |
The practical reading: a cubin-only build loads only within its major version, while a build that also ships PTX runs on newer GPUs without a rebuild. That JIT path has a driver requirement of its own, covered below.
Setting the compute capability target when you build
NVIDIA’s compatibility guide notes that minor-version compatibility requires passing the target architecture to nvcc, for example nvcc -arch=sm_xx. NVIDIA’s own example uses compute_80 for the PTX level and sm_120 for the later GPU it JIT-compiles to.
Shipping a cubin for each architecture you deploy on, plus PTX at the lowest compute capability you support, lets the build load on those GPUs and JIT on newer ones. Avoid a-suffixed targets in anything that must move between architectures, since their features are not guaranteed on later compute capabilities.
One more build detail affects deployment. nvcc links the CUDA runtime statically by default on non-Windows platforms (Windows defaults to a hybrid loader), and NVIDIA notes that CUDA applications typically include the libraries they need statically, so they should work on newer drivers.
Driver, toolkit and compute capability depend on each other
A compatible card is necessary but not sufficient. NVIDIA states that running a CUDA application requires a CUDA-enabled GPU and an NVIDIA driver compatible with the CUDA Toolkit used to build the application. That is why we keep the CUDA driver and CUDA Toolkit apart: the driver must be compatible with the toolkit that built the application.
Backward compatibility is the long-standing direction. Drivers have always been backward compatible with CUDA: a CUDA 11.0 application works with R450 and later drivers. The driver keeps supporting applications built on older toolkits.
Since CUDA 11, an application built with any toolkit release in a major family can run, with a limited feature set, on a system that has at least the minimum driver for that family, even if it differs from the driver bundled with the toolkit. NVIDIA’s CUDA Compatibility guide gives these minimums:
| CUDA Toolkit | Minimum driver | Upper range for minor-version compatibility |
|---|---|---|
| CUDA 13.x | >= 580 | N/A (backward compatibility applies for newer drivers) |
| CUDA 12.x | >= 525 | < 580 (newer drivers still supported through backward compatibility) |
| CUDA 11.x | >= 450 | < 525 (newer drivers still supported through backward compatibility) |
PTX is the caveat here. Applications that compile device code to PTX will not work on older drivers, and if the application needs PTX the driver has to be upgraded. The forward-compatibility story from the previous section therefore assumes a driver new enough to JIT the PTX you shipped.
Forward compatibility across major driver families is a narrower case. NVIDIA’s CUDA Compatibility Package (cuda-compat-<major>-<minor>) lets applications built with a newer toolkit run on an older Linux driver from a different major family, but only on NVIDIA data-centre GPUs, select NGC Server Ready RTX SKUs and Jetson boards. Consumer video cards outside those categories are not covered by this package. The full interaction of these axes is laid out in the four-axis CUDA compatibility matrix.
Checklist: is this card compatible with this build?
Run these in order; each step assumes the one before it passed.
- Confirm the GPU is NVIDIA and read its compute capability with
nvidia-smi --query-gpu=name,compute_cap. - Check the application or framework build contains a cubin for that major version at an equal or lower minor version, or PTX at an equal or lower compute capability.
- Check the driver meets the minimum for the toolkit’s major family (450, 525 or 580 for CUDA 11.x, 12.x and 13.x).
- If the build relies on PTX JIT, confirm the driver is new enough to compile it, and upgrade it if not.
- If the kernels use bfloat16 or an
a-suffixed architecture-specific target, confirm the card’s compute capability supports those features.
Compatible tells you it runs, not how well it runs
The checks above are about whether the code loads. They say nothing about whether the card is a good choice for the workload; that context comes from profiling, not spec tables. Our position is that vendor-specific APIs are not magically faster than standard ones, that the deeper optimisation they expose needs real commitment to pay off, and that profiling, not blog posts, supplies the context for judging it.
Compute capability narrows the shortlist and the profiler settles it. For the broader buying decision, see our decision framework for choosing hardware for AI. When a deployment runs on compatible hardware but misses its latency or cost target, finding the bottleneck is the job of TechnoLynx’s GPU performance engineering work.