For a manufacturer’s first quality-inspection or predictive-maintenance model, the MLOps practices that matter fit on a short list. You need versioned data, models and code. You need a pipeline that can rebuild and test the model, monitoring of both the input data and prediction quality, a defined response to drift with a human signing it off, a release gate the model must pass, a prepared rollback, and a named owner for each of these once the project team leaves. MLOps consulting is useful to a manufacturer when it installs that set at the right size and leaves the plant’s own people able to run it. Its value is low when it delivers a platform nobody on site can operate.
The risk runs in both directions. Many teams install enterprise-grade MLOps infrastructure long before they deploy their first production model, and spend months on platform work before any model delivers value. Having no infrastructure discipline at all creates fragility that is expensive to unwind once the model becomes business-critical. In a factory, “business-critical” can mean a reject decision on every part coming off the line. That makes the middle ground the only sensible place to start.
The MLOps practices a first manufacturing model actually needs
Kreuzberger, Kühl and Hirschl (2022) list CI/CD automation for the build, test, delivery and deploy steps, together with versioning of data, model and code, which supports both reproducibility and the traceability that compliance and audit require. Their list also includes continuous training (periodic retraining on new feature data, always with an evaluation run), continuous monitoring of data, model, infrastructure and serving performance, and feedback loops that carry monitoring results back to the retraining scheduler. A model registry stores trained models centrally with their metadata, including whether each version is in staging or production.
How much of that to automate on day one is a separate question. Google Cloud’s architecture guidance describes a starting level (level 0), where a trained model is deployed as a prediction service. The next level deploys a whole training pipeline with automated data and model validation, triggers and metadata management. Our recommendation for a first project: run every practice in some form, but automate only the ones that run often or fail expensively. The question that decides whether a first MLOps project survives production is which capabilities a team genuinely needs, and which tools assume a data-engineering maturity the organisation has not yet built. We go through that trade-off in more detail in our piece on the pros and cons of MLOps tools.
| Practice | What it protects against on a line | Right-sized first version |
|---|---|---|
| Versioning of data, model, code and config | Not knowing which model made a reject decision | Git for code and config, immutable dataset snapshots, model version tags |
| Model registry | Deploying the wrong artefact, or being unable to find the last good one | One registry with staging and production status |
| Build-and-test pipeline (CI/CD) | Untested changes reaching the edge device | Scripted build, test and deploy; adapted CI tools are acceptable |
| Input and quality monitoring | Silent decay from sensor, lighting or material changes | Schema and value checks on inputs, plus tracked precision and recall where labels arrive |
| Retraining with evaluation | A model trained on last year’s conditions | Triggered or scheduled retraining, with an evaluation run before promotion |
| Release gate and rollback | A worse model replacing a working one | Automated bless-or-veto checks and a pointer to the previous model |
The question of what MLOps infrastructure is needed, and when gets its own treatment elsewhere. On this page the point is narrower: every row above can start small, but none can be skipped.
Check the data and the tolerance for error before choosing a model
Check the data first: its quality and quantity, whether the processes generating more of it are accessible, and what the business expects. Near-100% accuracy is almost never a plausible target, so the workflow has to tolerate faults and there must be appetite for a human in the loop. Searching for the perfect model before understanding the business value being optimised, and before any field testing, is time badly spent.
A review of ML robustness in production attributes many robustness problems to faulty sensors, corrupt, missing or manipulated data, and drift, rather than to the choice of algorithm. The same review notes that external effects such as temperature, humidity, machine health and material variation significantly affect product quality. In injection moulding, for example, process parameters alone cannot estimate quality. Class imbalance is the other trap. Quality-control data is skewed towards good parts, and a model that passes a faulty part damages the quality function’s reputation.
None of this is an MLOps tool problem. Monitoring cannot rescue a model whose training data never contained the defect class, so a data audit comes before any pipeline is built. A survey of deployment case studies also notes that simpler models are often chosen in practice to get the end-to-end setup in place and start collecting feedback. Hansson et al. describe several manufacturing cases that adopt decision trees for their interpretability.
How does drift break an inspection or maintenance model on a production line?
Drift degrades these models over time. ML models are trained on static data, so when the underlying distribution changes through external effects or environmental shifts, their performance deteriorates over time. The same review states that in manufacturing, concept drift is an expected phenomenon rather than an edge case, and that experts need to explain it for future models to stay adaptable. Undetected concept drift can have major adverse effects on model performance. It can arrive as a discrete event or as a gradual change.
The two model families drift in different ways:
- Predictive maintenance: a machine’s operating modes and health change over time. AWS’s Lookout for Equipment documentation calls retraining the preferred response to that data drift. Zenisek et al. go further and treat detected concept drift in sensor streams as a possible early sign of malfunction, rather than only as a modelling problem.
- Visual inspection: environmental or material changes can shift the input data over time, and the model’s performance deteriorates with it.
- Pipeline-level breakage: data pipelines can fail silently through schema drift, rising null counts, changed units or value standards, and changes in data volume.
The retraining trigger should be explicit. Retraining can fire when a statistical drift threshold is crossed, when new feature data arrives, or on a fixed schedule. Google Cloud’s guidance draws a useful distinction. A schema anomaly in incoming data should stop the pipeline so people can investigate, whereas a significant shift in data values is a cue to retrain. In the Industry 4.0 companies Faubel and Schmid studied, automated retraining was “still in its infancy”.
Manufacturing has a specific reason to keep a person in the retraining loop. One company in the same study described an operator physically changing something in the plant so that the model no longer fitted. Retraining automatically on that new state, with no human involved, can be the wrong response. The same interviews describe slow problems, such as ageing plant or valves that are no longer linear, where it is unclear whether the model or the underlying data is at fault. Those cases still need humans to detect them. Retraining can be automated. Promoting the retrained model onto a live line should wait for a sign-off from someone who knows what changed on the floor. Lookout for Equipment formalises the same choice: its manual mode holds a retrained version until a user activates it, while managed mode activates it automatically if its metrics beat the current version.
When is a model ready to go onto a live line? A release-gate checklist
A model is ready for a live line when it has passed an offline gate against the model it would replace, and then survived limited exposure to real production before taking full traffic. Google Cloud’s guidance is explicit: evaluate the new model on a test set, compare it with the current production or baseline model, and promote it only if it performs better. After that, run online validation in a canary or A/B setup before it serves all traffic.
The gate should be automated, and it needs two kinds of threshold. Breck et al. describe a system that inspects every trained model before it touches real traffic and either blesses or vetoes it. They recommend loose thresholds against a validation set to catch slow degradation across many versions, and tighter thresholds against the previous model to catch sudden drops. Looking at slices of the data matters. A global metric can improve while quality on one important subset collapses, and release tests can impose both absolute and incremental limits per slice. For an inspection model, a slice might be a product variant, a shift or a camera station.
Readiness checklist for a manufacturing quality or maintenance model:
- Data audit done: defect classes represented, external factors such as temperature and material recorded, known class imbalance documented.
- Offline validation beats the current model or an agreed baseline on the test set.
- Slice-level thresholds pass for each product variant or station, and nothing collapses inside a better global number.
- Staleness understood: the team knows how quickly quality falls as the training data ages. Breck et al. suggest an A/B experiment with older models to draw an age-versus-quality curve.
- The model loads in the production serving environment and produces the expected predictions on real data.
- A monitoring strategy, naming the elements to monitor, is defined before go-live.
- The previous model version is one step away, so rollback is possible.
- Approval is documented under a quality gate with segregation of duties.
Breck et al.’s ML Test Score measures how ready an ML system is for production. Each test scores half a point if run manually with documented results and a full point if automated. The final score is the minimum across the data, model, infrastructure and monitoring sections, so a strong model cannot hide weak monitoring. The authors note that systems at different stages may reasonably aim for different scores. That gives a first project a fair way to be “basically productionised” without pretending to be mission-critical. Monitoring and release readiness are an engineering discipline of their own, separate from model accuracy: the deliverables are eval harnesses, regression suites, drift detection and release-readiness reviews, not a dashboard.
Canary, blue/green and shadow: choosing a rollback strategy
The strategy should follow the application’s criticality and risk tolerance. AWS’s Well-Architected ML Lens describes four options. Blue/green keeps two identical environments for instantaneous rollback. Canary sends a small share of traffic to the new model. A/B compares metrics between versions. Shadow runs the new model alongside production without using its predictions. AWS names canary or shadow deployments as more cautious approaches for high-stakes applications.
On a production line, shadow mode has a particular appeal. A new inspection model in shadow mode scores parts alongside the current one without its predictions being used. One proposed platform takes this further, running shadow versions next to the active one, measuring safety metrics, and activating the update only if it outperforms the current version.
Rollback depends on preparation more than on the deployment pattern. AWS advises defining specific metric thresholds that trigger a rollback, and establishing the procedure in advance. Version control of every input to training gives a team the ability to return to the last known working system, which improves fault tolerance. Beware the update that is more accurate but behaves differently. Survey work cites findings that raising accuracy at the expense of compatibility with users’ expectations can degrade overall human-AI team performance.
Edge, OT and IT: what manufacturing adds to standard MLOps
The AIM4M authors (2025) identify technical complexity, a lack of implementation standards and fragmented organisational processes as the reasons AI stalls beyond the prototype, especially in cyber-physical production systems. Their process model adds roles that come from OT/IT convergence, namely hardware development, hybrid testing and operation within a production system, plus roles for compliance and audit. It requires governed updates in operation: continuous monitoring, drift detection, retraining and redeployment through reusable pipelines, controlled rollout such as canary, and rollback, all gated by approvals. Quality gates before development, at release and at each update enforce documented approvals and segregation of duties.
The edge adds its own constraint. A multivocal review notes that in distributed edge deployments, model selection depends on the heterogeneous devices the model runs on, and retraining may need to happen in a decentralised way from streaming data. It also points to MLOps extensions built specifically for manufacturing’s distributed edge-cloud environments. In practice, this means the release gate has to test the model on the actual line-side hardware and runtime. Passing in the cloud is not enough. Keeping software dependencies and configuration consistent from training through staging to production is critical for deep learning models, and infrastructure-as-code is one practice that addresses it.
Who owns monitoring, retraining and rollback after the consultants leave?
Ownership has to be named per activity before handover, not discovered at the first incident. MLOps engineers are primarily responsible for monitoring, and they step in when retraining is needed because of data shifts. Some studies describe an operations team that takes over after the model is handed on, owning packaging, release and continuous performance monitoring. ML engineers and data scientists stay involved in early monitoring to handle model or feature optimisation. AIM4M asks for domain-specific roles across OT/IT, quality and compliance, each with a lead or contributor assignment at every process stage.
| Activity | Suggested owner on site | Must also be involved |
|---|---|---|
| Input and quality monitoring, alert triage | MLOps or operations engineer | Line or process engineer to explain physical changes |
| Deciding to retrain | MLOps engineer | Process owner who knows whether the plant changed |
| Promoting a retrained model | Release authority under a quality gate | Quality function, for segregation of duties |
| Rollback | Operations or ML engineer running the deployment | Whoever defined the rollback thresholds |
One warning from Breck et al. applies directly to plants that feed models from a wider data platform. Teams assumed that an upstream service would catch problems in their data, or that a larger system’s reliability engineers would notice their errors, and both assumptions can fail when a small system’s errors are masked in a big system’s noise. A quality-inspection model needs its own monitoring and its own named contact.
This is where an MLOps consulting engagement either succeeds or quietly fails. Exit criteria matter more than entry scope: the engagement should transfer capability, not create a permanent reliance on outside expertise. Handover should count as done only when the site team has run a retrain, a promotion through the gate and a rollback themselves.
What an MLOps consultant delivers that an in-house data team often lacks
Building a good model is only part of the job. What tends to be missing is production readiness and the roles needed to operate it. Kreuzberger et al. (2022) observe that many ML proofs of concept never reach production, because the field has focused on building models rather than on production-ready products and the roles needed to run them. The Industry 4.0 companies Faubel and Schmid studied had a dedicated MLOps team and a well-defined deployment process. Where a manufacturer has neither yet, a consulting engagement should transfer capability rather than create reliance on outside expertise.
Who can set up MLOps for our inspection and maintenance models?
TechnoLynx’s MLOps engineering team sets up monitoring, a release gate and rollback around a manufacturer’s quality-inspection or predictive-maintenance model. When choosing a partner, judge them on the exit criteria they commit to, not only on the entry scope.
The limits are real. This engineering work is not safety certification or regulatory sign-off, and it does not replace the plant’s quality function. It is also the wrong engagement for a proof of concept that has not yet earned a production slot. A team that needs hands to build features, or the cheapest possible build, is better served by contractors. Managed ML platforms are an alternative for the operational maintenance of models. They provide data storage, retraining, deployment and common health metrics out of the box, which greatly reduces operational burden. Equipment-monitoring services with built-in retraining modes are another option. Our broader article on when to engage MLOps consulting and how to avoid dependency covers the commercial side. For a plant starting from zero, the guide to MLOps for organisations that have never operationalised a model is the better first read.
The test that matters six months after go-live
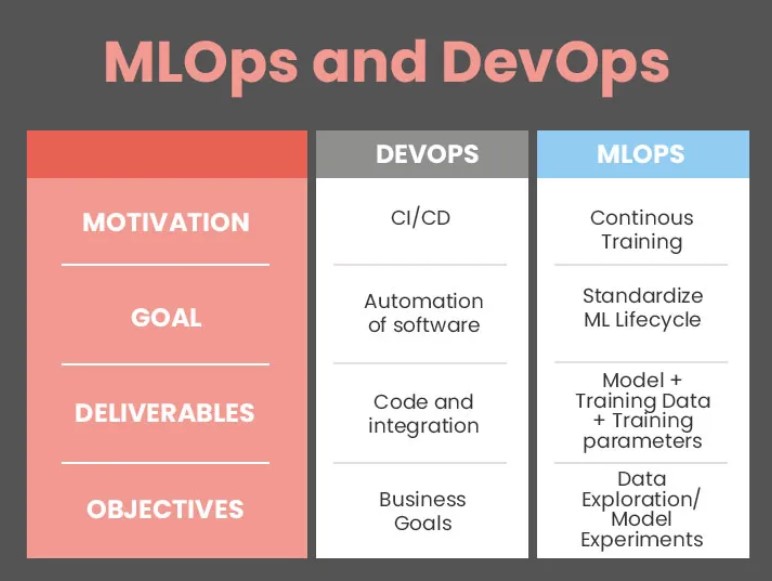
The real measure of an MLOps setup on a production line is not the launch. It is the first time the plant changes under the model, through a new supplier, a recalibrated sensor or a worn valve. At that point someone on site has to notice the shift, decide whether it is drift or a deliberate change to the plant, retrain or roll back, and get the new version through the gate without calling the people who built it. If that sequence is not yet written down with names against each step, the model is deployed but not yet operated, and that gap is the thing to close before adding any more tooling. How MLOps works as an operating model rather than just DevOps for models is the broader frame for that judgement.