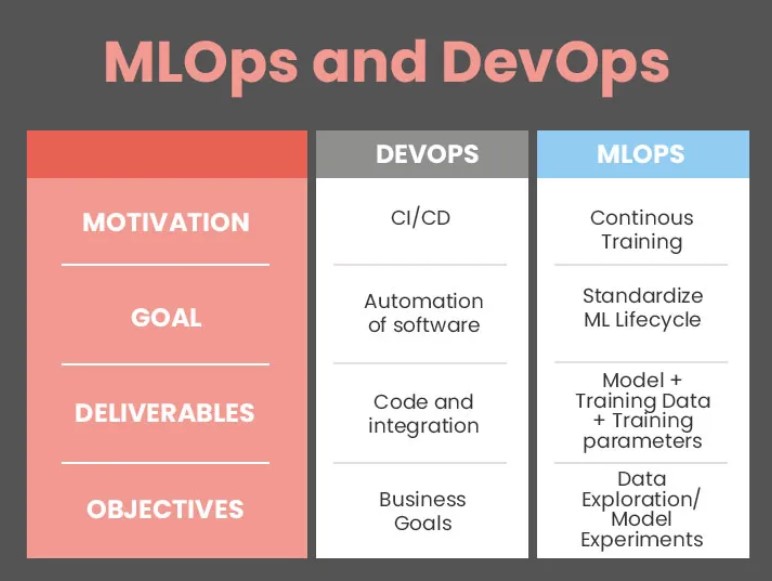
MLOps applies DevOps principles (versioning, CI/CD and monitoring) to machine learning, so that models reliably ship to production and stay accurate once real traffic reaches them. MLOps tools and frameworks automate the machine learning lifecycle, from data preparation and training to deployment, monitoring and governance. A small team does not need every tool category at once. Experiment tracking and a registry come first, and the rest is added as MLOps maturity grows.
Why a model in production needs more than the model
The training code is only part of a production ML system. Sculley et al. (NeurIPS 2015), as cited by GrowthGear, found that ML code can be as little as 5% of a real-world ML system, with the rest being the infrastructure around it. That surrounding infrastructure is what MLOps manages.
Models also decay in more ways than conventional software. Google Cloud’s architecture guidance points out that ML models can lose performance not only through bad code but because the data they see keeps changing, so a team has to track summary statistics of its data and monitor online performance in order to alert or roll back when values deviate. A model that performed well in testing can quietly get worse in production.
The third pressure is reproducibility. A model built in an isolated notebook is hard to rebuild, and versioning data, code and models together lets a team replicate an experiment exactly, which matters both for debugging and for anyone auditing a decision later. Shankar et al. (2022), interviewing ML engineers, named three variables that govern whether a production deployment succeeds: velocity, validation and versioning.
MLOps tools and frameworks by lifecycle stage
Shankar et al. describe operationalising ML as a continual loop of data collection and labelling, experimentation, evaluation through a multi-staged deployment, and monitoring for performance drops in production. The table lists the tool categories by lifecycle stage, with example tools for each.
| Stage | What the tool category does | Example tools |
|---|---|---|
| Data and model versioning | Versions large datasets and model files alongside code, so any run can be rebuilt | DVC |
| Experiment tracking | Logs hyperparameters, metrics, code versions and artifacts for every training run, so runs can be compared and reproduced | MLflow Tracking, Weights & Biases |
| Model registry | Stores model versions with lineage and status, and acts as the handoff point between training and serving | MLflow Model Registry, SageMaker AI Model Registry |
| Pipelines and orchestration | Runs preprocessing, training and evaluation the same way every time | Airflow, Kubeflow Pipelines, DVC pipelines |
| CI/CD for ML | Validates data, schemas and models as well as code, and automates deployment of the prediction service | CML (on GitHub or GitLab actions), Azure DevOps pipelines |
| Serving | Exposes the model as a service and handles autoscaling, health checks, versioning and rollback | KServe, MLflow serving integration |
| Monitoring | Tracks production performance, detects data and model drift, and triggers retraining | Evidently, SageMaker AI Clarify |
One survey of MLOps platforms compared them on data versioning, hyperparameter tuning, model and experiment versioning, pipeline versioning, CI/CD, deployment and performance monitoring. The same survey notes that MLOps still lacks mature single solutions, so teams assemble a set of tools, while the cloud providers offer integrated platforms such as Google Cloud’s AI Platform, Azure ML studio and Amazon SageMaker.
MLflow for tracking and the registry
MLflow, originally developed by Databricks, is framework-agnostic and integrates with PyTorch, TensorFlow, scikit-learn and XGBoost. Its Tracking component is an API and UI for logging parameters, code versions, metrics and output files, organised around runs, and its Model Registry is a central store that records lineage, versions, aliases and tags for each model. One practical detail catches teams out: the MLflow documentation states that the Model Registry needs a database-backed store such as PostgreSQL, and a model must be logged with the log_model method of its flavour before it can be registered.
The registry also supports aliases. An alias is a mutable, named reference to a specific model version, so serving can pull @champion or @staging instead of a file path, and promotion becomes a recorded change in the registry rather than someone copying a file.
DVC for data and model versioning
DVC extends Git to handle large files, datasets and models, with storage backends including S3, Google Cloud Storage and Azure Blob. Large files are replaced in the repository by small metafiles that point to the data stored elsewhere, so the team keeps a normal Git workflow without putting gigabytes into Git. DVC also defines pipelines and tracks experiments. Its limit is clear: DVC covers versioning and pipelines, and serving and monitoring need separate tools.
Which MLOps tools does a small team actually need first?
Start with experiment tracking, add a model registry, and expand only as maturity grows, because every additional tool category brings integration work and operational overhead. MLflow and Weights & Biases keep appearing as starting points because they slot into an existing workflow with little infrastructure change. MLflow is Apache 2.0 licensed and self-hosted, covering tracking and the registry without licensing fees.
Self-hosting still needs engineering time to maintain. GrowthGear’s guidance is that teams under five people with no dedicated infrastructure engineer should default to a managed platform tied to their existing cloud, and that self-hosting MLflow pays off once someone has time to maintain it. We would weigh that the same way: the licence cost is zero, but the database, the artifact store, upgrades and access control are somebody’s job.
On sequencing, GrowthGear lays out a realistic rollout of about 90 days: experiment tracking in month one, a model registry and reproducible pipelines in month two, then basic CI/CD and monitoring in month three. The argument for that order is that each phase builds on the one before, and that it beats adopting a full enterprise stack before there is a second model in production.
Kubeflow runs on Kubernetes, and Airflow or Kubeflow Pipelines are suggested only if the infrastructure supports them. In our judgement a team should adopt Kubernetes for serving when its scaling needs ask for it, not because an MLOps diagram shows it. AWS makes a similar point about components generally: a feature store may be needed for low-latency personalisation and not needed for other use cases.
How tracking, registry, CI/CD and monitoring keep a model reliable
The four phases combine into one control loop. Tracking gives every model a traceable origin, since each registered version links back to the run that produced it, with its data and parameters. The registry turns “we think this one is better” into a quality gate with explicit promotion criteria. CI/CD enforces the gate: in AWS’s reference workflow with SageMaker AI and Azure DevOps, the build pipeline registers a model only if it meets an accuracy condition, and the deploy pipeline starts when a model is approved, deploys to staging, runs automated tests and waits for manual approval before production. Google’s guidance adds that a newly trained model is validated offline against the current production model and promoted only if it performs better.
After launch, the deployment pattern decides how much production traffic is at risk during a rollout. MLflow’s serving guide describes canary releases, where typically 1-10% of traffic goes to the new version and traffic shifts back automatically if the canary degrades. AWS’s Well-Architected ML Lens adds blue/green deployments for instant rollback.
Monitoring closes the loop by watching for drift. Feature drift is a change in the input distribution, while concept drift is a change in the relationship between inputs and the outcome, and the second usually means the model has learned an outdated pattern. Tests such as PSI and KS make drift visible even when labels are missing, but a statistical signal is not a production risk on its own: a large shift in a low-importance feature can be noise, and a small shift in a high-impact feature can matter a lot. MLflow’s guide advises starting with a simple statistical test, accepting some false positives and tuning thresholds over the first month rather than waiting for a perfect system. A monitoring tool only pays off when its alerts are wired to the registry and the deploy pipeline.
When is a team ready to invest in MLOps instead of deploying by hand?
The readiness signal is not team size but repetition: once a model has to be retrained and redeployed on a schedule or on new data, manual steps become the risk. Google Cloud’s guidance defines level 1 as continuous training through an automated pipeline, which needs automated data and model validation, pipeline triggers and metadata management. Microsoft’s Azure maturity model defines five levels of capability, rising from automated training with centralised tracking, to automated deployment with CI/CD, full traceability and registries, to full MLOps where drift or regression signals trigger retraining and promotion is policy-based.
Signals that a team has outgrown hand deployment, as we would read them:
- Nobody can say with certainty which data and code produced the model currently serving.
- A second or third model is heading to production and each was deployed differently.
- Retraining happens because someone remembered, not because a trigger fired.
- A bad release would be rolled back by redeploying an old file found on a laptop.
For teams that recognise one or two of these, the right move is tracking plus a registry, not a platform.
Choosing the stack is the easy half
Most of the tool decisions above are reversible: MLflow, DVC, Evidently and the cloud platforms can be swapped with some pain. What is hard to reverse is a pipeline where promotion criteria were never written down, because every later tool inherits that ambiguity. The question to settle before picking any tool is what evidence a model must produce before it serves traffic, and who or what is allowed to approve it. Teams that want engineering help putting that gate, and the stack around it, into production can see how we approach it on our MLOps engineering page.
Sources
- Best MLOps Tools for Small AI Teams, ai.growthgear.com.au
- Top MLOps Tools, everpuredata.com
- MLOps: Continuous delivery and automation pipelines in machine learning (Google Cloud Architecture Center), docs.cloud.google.com
- Operationalizing Machine Learning: An Interview Study (Shankar et al.), arxiv.org
- Data Version Control (software), en.wikipedia.org
- ML Experiment Tracking, mlflow.org
- MLflow Model Registry documentation, mlflow.org
- Build an MLOps workflow by using Amazon SageMaker AI and Azure DevOps - AWS Prescriptive Guidance, docs.aws.amazon.com
- Model Serving Infrastructure: A Practical MLOps Guide, mlflow.org
- Machine Learning Operations: A Survey on MLOps Tool Support, arxiv.org
- MLREL04-BP02 Use an appropriate deployment and testing strategy (AWS Well-Architected ML Lens), docs.aws.amazon.com
- Model drift monitoring is essential for reliable ML production systems, nhimg.org
- MLOps Maturity Model (Azure Architecture Center), learn.microsoft.com